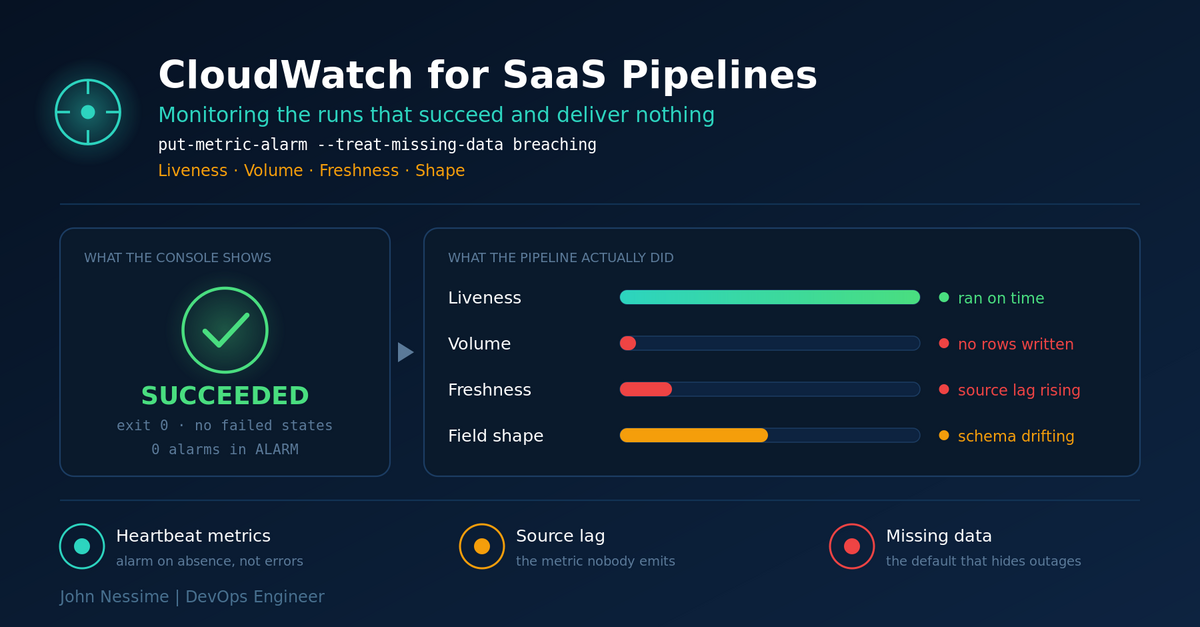
CloudWatch Data Pipeline Monitoring: Catching the Runs That Succeed and Deliver Nothing

Your SaaS pipeline will fail far more often by succeeding at nothing than by throwing an exception, and every CloudWatch default treats an absent metric as a non-event. Here are the four signals worth alarming on: liveness, volume, freshness and shape, plus the missing-data traps that leave alarms permanently green.
Continue ReadingCloudWatch Data Pipeline Monitoring: Catching the Runs That Succeed and Deliver Nothing

Optimizing API Calls to Reduce SaaS Costs: Six Levers That Actually Move the Bill

Third-party API spend is the one production signal with no error rate attached to it, which is why it creeps up quietly. This is a working engineer's guide to reducing SaaS API costs by changing the shape of your calls: reading the billing unit before you optimise anything, killing pointless polling with conditional requests and webhooks, collapsing N+1 patterns, caching with stampede protection and per-tenant keys, stopping your own retry amplification, and attributing spend so you can prove the work paid off.

Continue ReadingOptimizing API Calls to Reduce SaaS Costs: Six Levers That Actually Move the Bill

GitLab CI vs GitHub Actions vs Jenkins: Choosing Without Regretting It Later

A practical comparison of GitLab CI, GitHub Actions and Jenkins that skips the feature table. What actually decides the choice is where your code lives, whether the runner can reach the deploy target, and who owns the control plane at 2am. Includes the cost mechanics, the security failure modes, and a decision procedure you can run in an afternoon.

Continue ReadingGitLab CI vs GitHub Actions vs Jenkins: Choosing Without Regretting It Later

Data Lake vs Data Warehouse for CRM Analytics: Volume Is the Wrong Question

Everyone argues this one on data volume, and volume is the argument that matters least: CRM data is small enough that both architectures handle it comfortably. What actually decides data lake vs data warehouse for CRM analytics is how much point-in-time history you need, how fast the schema churns, what shape your queries are, and who is going to maintain the thing. Includes a decision procedure you can run in an afternoon.

Continue ReadingData Lake vs Data Warehouse for CRM Analytics: Volume Is the Wrong Question

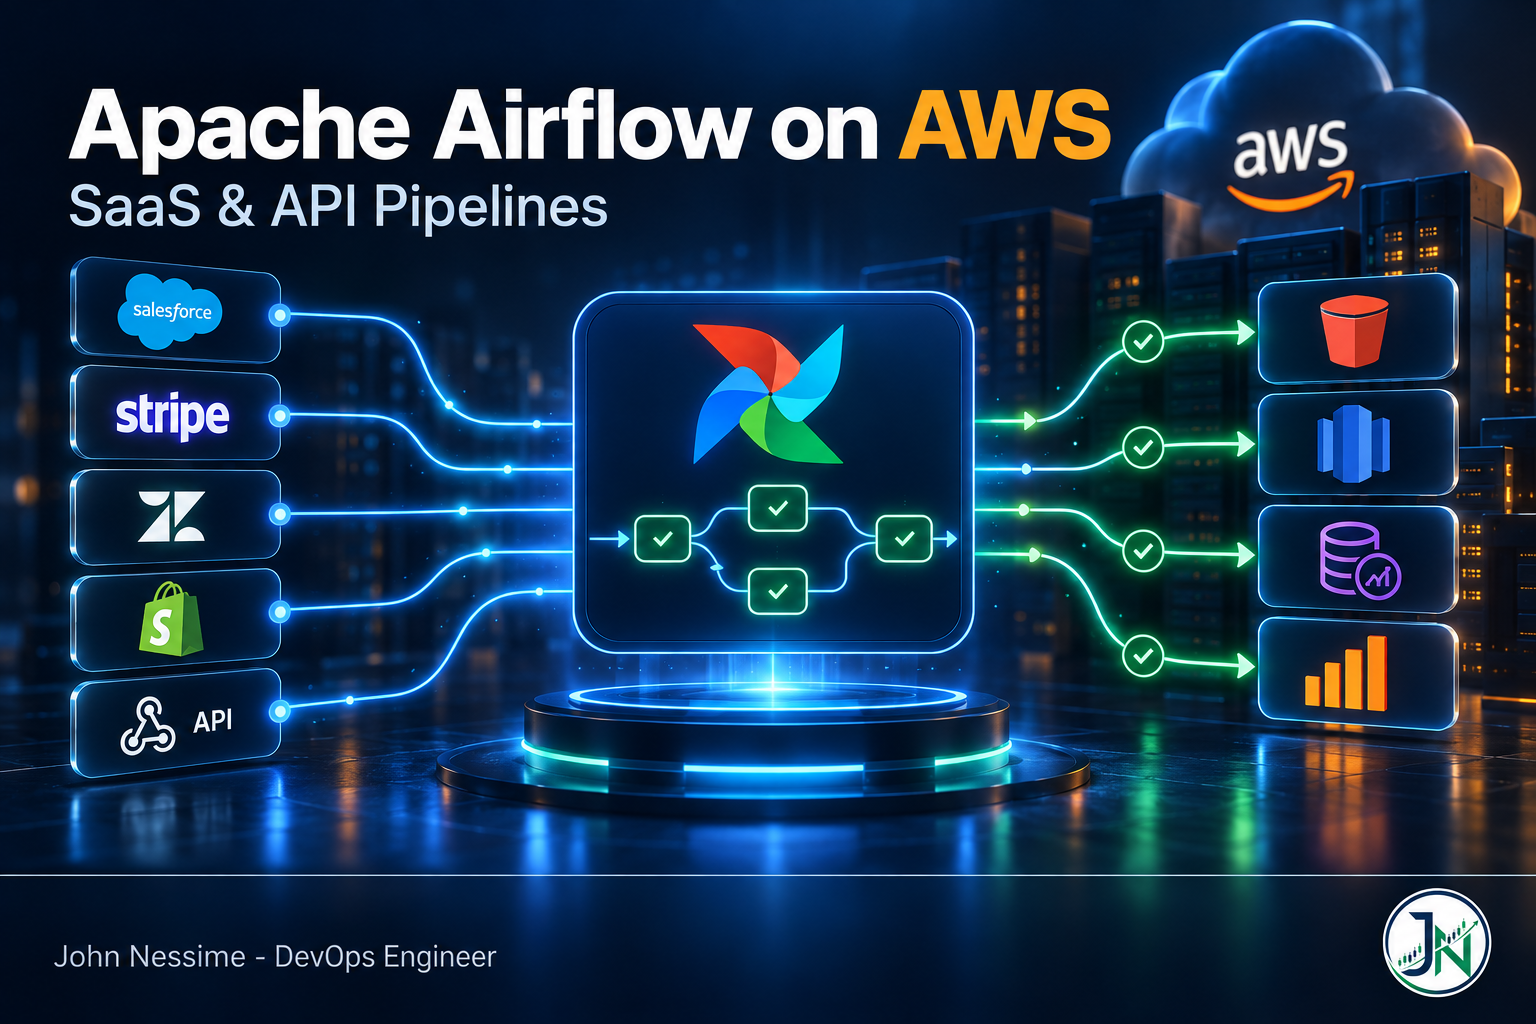
Apache Airflow on AWS: Building SaaS and API Pipelines That Don’t Lie to You

Most API pipeline failures are green DAGs producing incomplete data. A practical guide to running Apache Airflow on AWS for SaaS and API extraction: choosing between MWAA provisioned, MWAA Serverless and self-managed, the pool setting that silently stops throttling when you go deferrable, retry and pagination design, secrets handling, and the four cost lines that actually move.

Continue ReadingApache Airflow on AWS: Building SaaS and API Pipelines That Don’t Lie to You

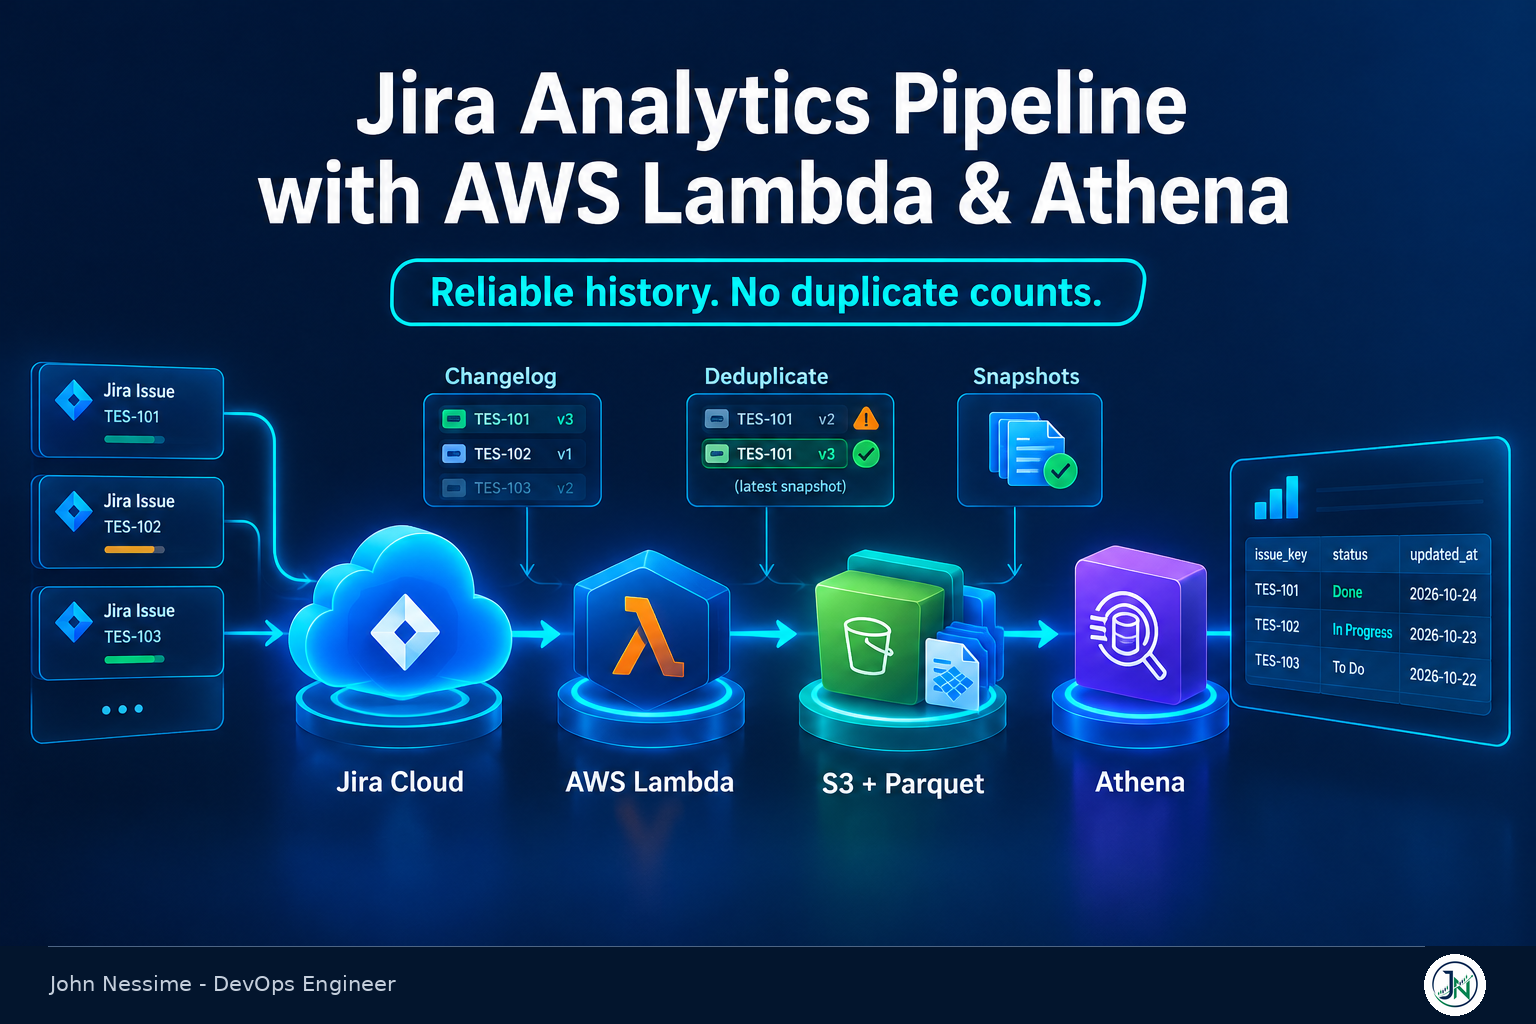
Building a Jira Analytics Pipeline with AWS Lambda and Athena (Without Double-Counting Everything)

Jira's built-in reports stop at the board boundary. This guide walks through a Jira analytics pipeline built on AWS Lambda, S3 and Athena, organised around the four failure families that actually bite: the removed search endpoint, silently truncated changelogs, incremental loads that duplicate rows, and an S3 layout that quietly inflates your query bill.

Continue ReadingBuilding a Jira Analytics Pipeline with AWS Lambda and Athena (Without Double-Counting Everything)