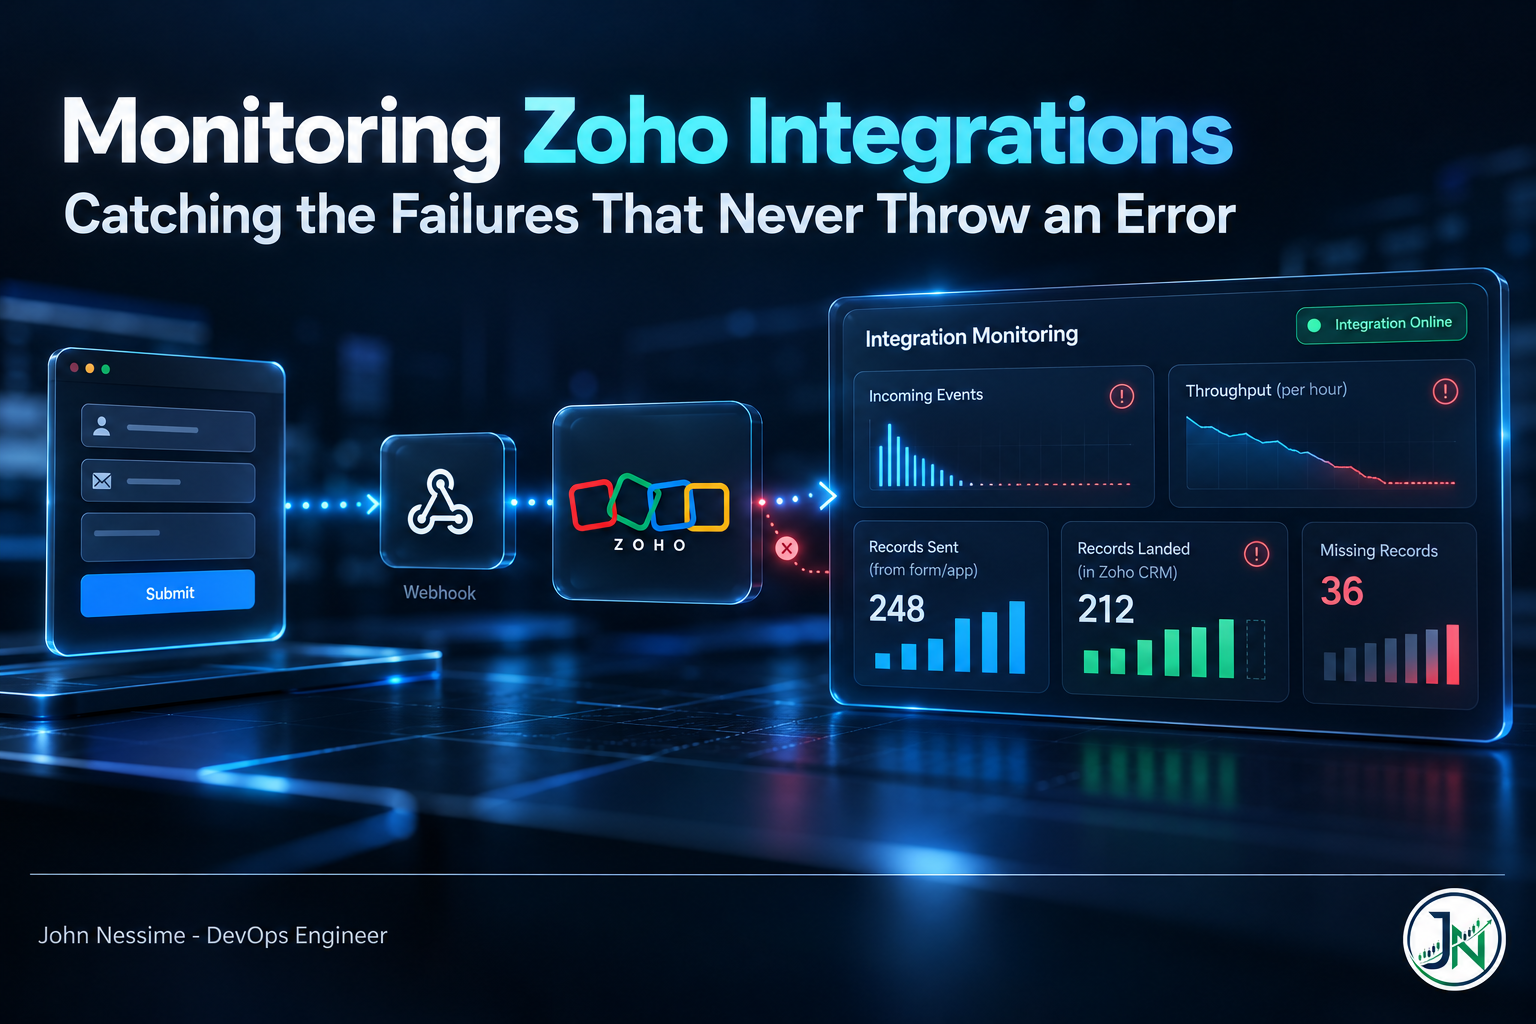
Monitoring Zoho Integrations: Catching the Failures That Never Throw an Error

Zoho integrations rarely fail loudly. Channels expire after an hour, credits drain against a rolling window, and bulk writes return HTTP 200 while rejecting records. Here is how to instrument for absence using CloudWatch Embedded Metric Format, Loki's absent_over_time, and Grafana across both.

Continue ReadingMonitoring Zoho Integrations: Catching the Failures That Never Throw an Error

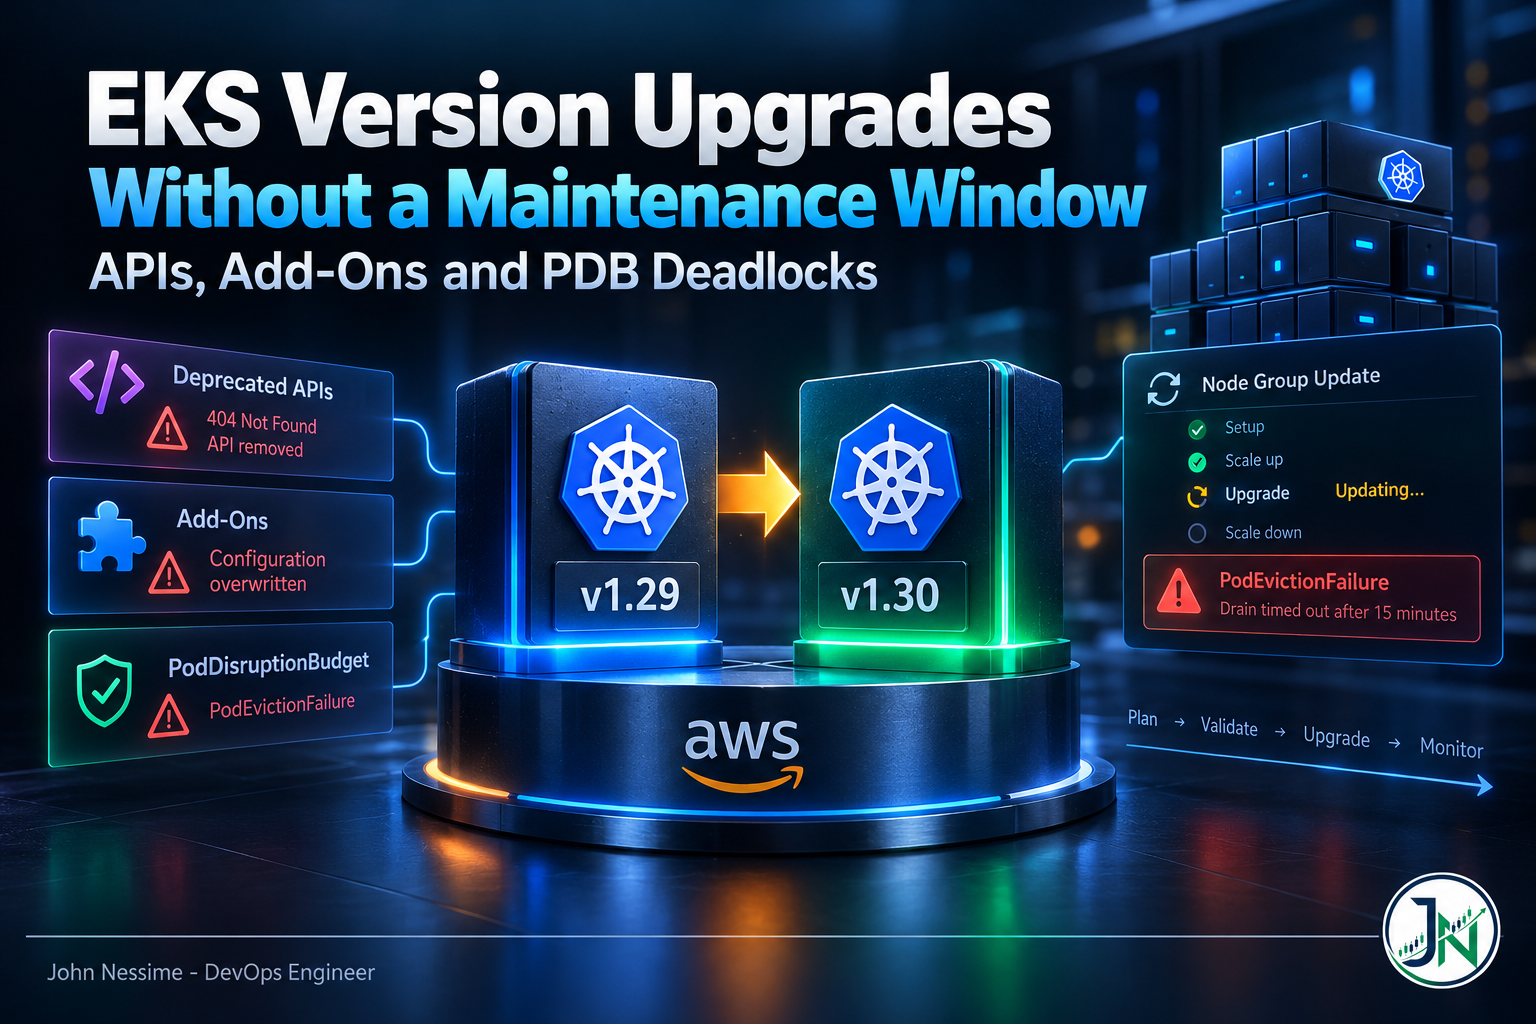
EKS Version Upgrades Without a Maintenance Window: APIs, Add-Ons and PDB Deadlocks

The control plane bump is the part AWS handles and almost never breaks. The damage happens in the data plane rollout afterwards. A practical walk through the three failure families that actually stall EKS version upgrades: removed APIs you did not know you were calling, add-on updates that silently discard your configuration, and pod disruption budgets that deadlock the node drain, plus what each escape hatch really costs.

Continue ReadingEKS Version Upgrades Without a Maintenance Window: APIs, Add-Ons and PDB Deadlocks

The Real Cost of CloudWatch: Logs, Metrics, Retention and Cardinality

CloudWatch rarely fails loudly, it accumulates. This is a breakdown of the four independent meters behind the bill: ingestion, storage, Logs Insights scans and custom metric cardinality. Why the same log line gets billed three times, why log groups never expire by default, how a single dimension can multiply your metrics bill without your traffic changing, and how to attribute the spend to specific log groups before you start deleting things.

Continue ReadingThe Real Cost of CloudWatch: Logs, Metrics, Retention and Cardinality

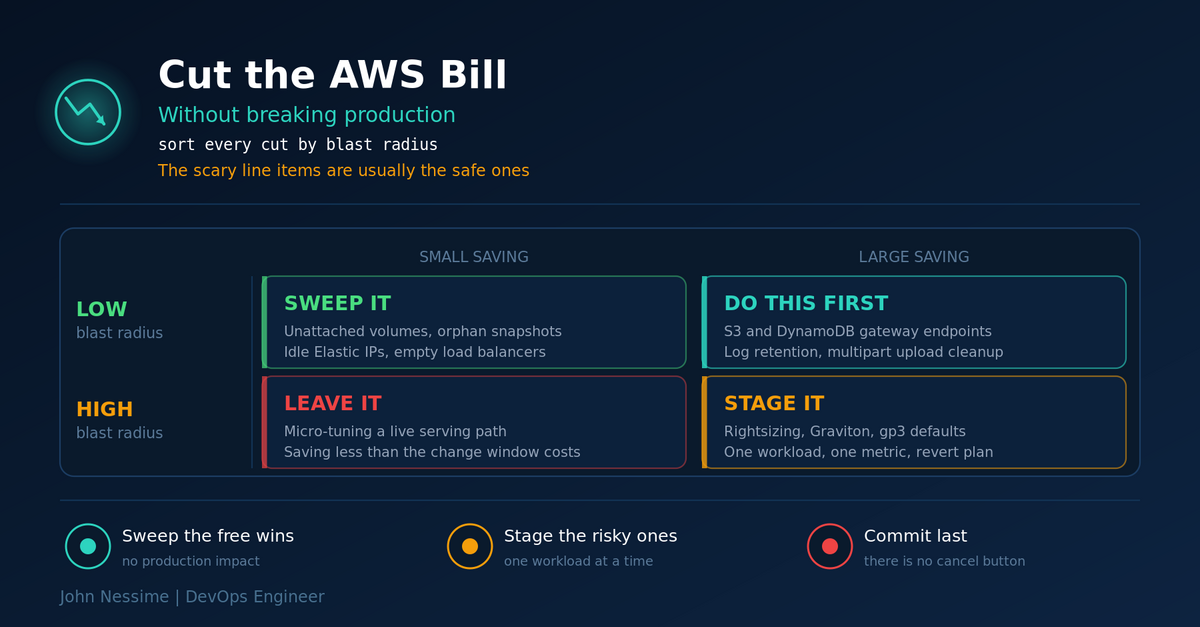
Cut AWS Costs Without Breaking Production: A Blast-Radius Playbook

Most AWS cost work goes wrong because it starts with the biggest line item, which is also the riskiest. Order the work by blast radius instead: free networking and storage fixes first, performance envelopes one workload at a time, and commitments last. Includes the commands to find the waste and the cuts that look harmless and are not.

Continue ReadingCut AWS Costs Without Breaking Production: A Blast-Radius Playbook

Grafana Monitoring for AWS Data Pipelines: The Green Dashboard Problem

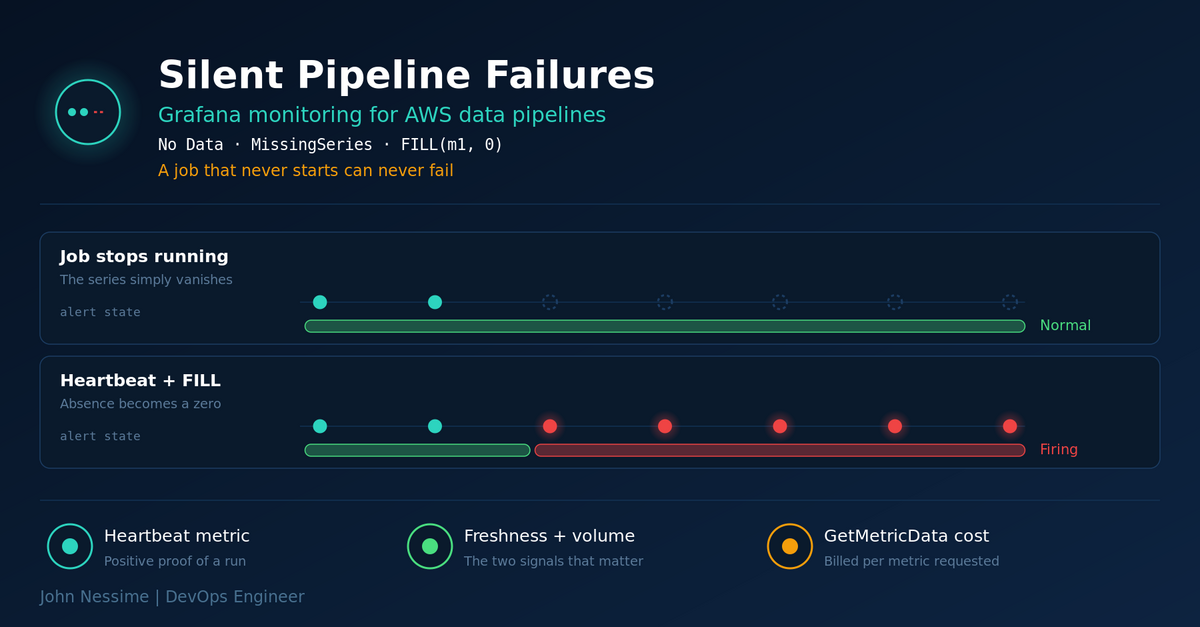
A Glue job that stops running emits no metrics, so the dashboard stays green and the alert quietly resolves itself. Here is why Grafana monitoring for AWS data pipelines misses that failure, and the heartbeat, metric math and no-data configuration that closes the gap, along with the CloudWatch query costs and IAM boundaries nobody warns you about.

Continue ReadingGrafana Monitoring for AWS Data Pipelines: The Green Dashboard Problem