Building a Hotel Data Lake on AWS That Agrees With the Night Audit

Hotel source data is mutable in the past, so an append-only pipeline drifts away from the PMS without anyone noticing until month close. A practical guide to room-night grain, bitemporal modeling with Apache Iceberg, PMS ingestion, guest data scope, and file physics at hotel volumes.

Continue ReadingBuilding a Hotel Data Lake on AWS That Agrees With the Night Audit

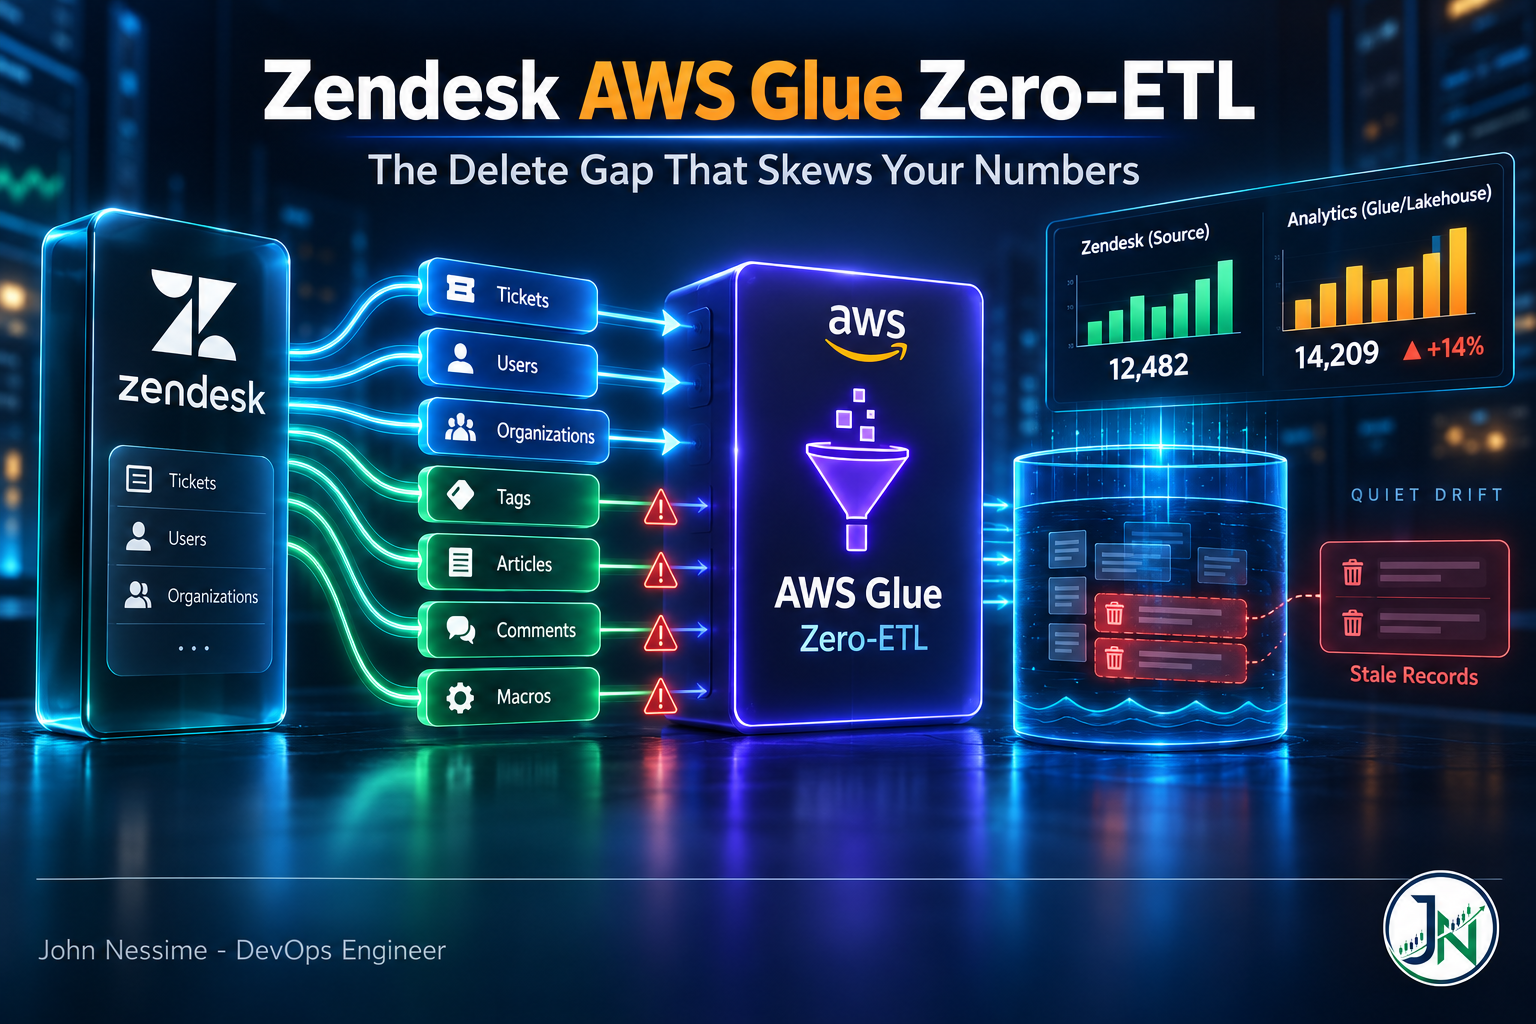
Zendesk Data Integration with AWS Glue Zero-ETL: The Delete Gap That Skews Your Numbers

AWS Glue zero-ETL replicates seven Zendesk entities, but only three of them ever remove a row. Here is how that gap quietly skews CSAT and knowledge base counts, plus the three IAM layers to wire, the two settings you cannot change after creation, and the CloudWatch metrics that make drift visible before someone spots it in a meeting.

Continue ReadingZendesk Data Integration with AWS Glue Zero-ETL: The Delete Gap That Skews Your Numbers

Data Lake vs Data Warehouse for CRM Analytics: Volume Is the Wrong Question

Everyone argues this one on data volume, and volume is the argument that matters least: CRM data is small enough that both architectures handle it comfortably. What actually decides data lake vs data warehouse for CRM analytics is how much point-in-time history you need, how fast the schema churns, what shape your queries are, and who is going to maintain the thing. Includes a decision procedure you can run in an afternoon.

Continue ReadingData Lake vs Data Warehouse for CRM Analytics: Volume Is the Wrong Question

Run It Twice, Get Two Answers: Building an ETL Pipeline From Zoho CRM to Amazon S3

You re-run the same extract for the same window and get a different set of rows. Nothing errored. You were paginating a result set that kept changing while you read it. Here's how to build a Zoho CRM to S3 pipeline whose runs are repeatable, from closed read windows to Bulk Read and deletions.

Continue ReadingRun It Twice, Get Two Answers: Building an ETL Pipeline From Zoho CRM to Amazon S3