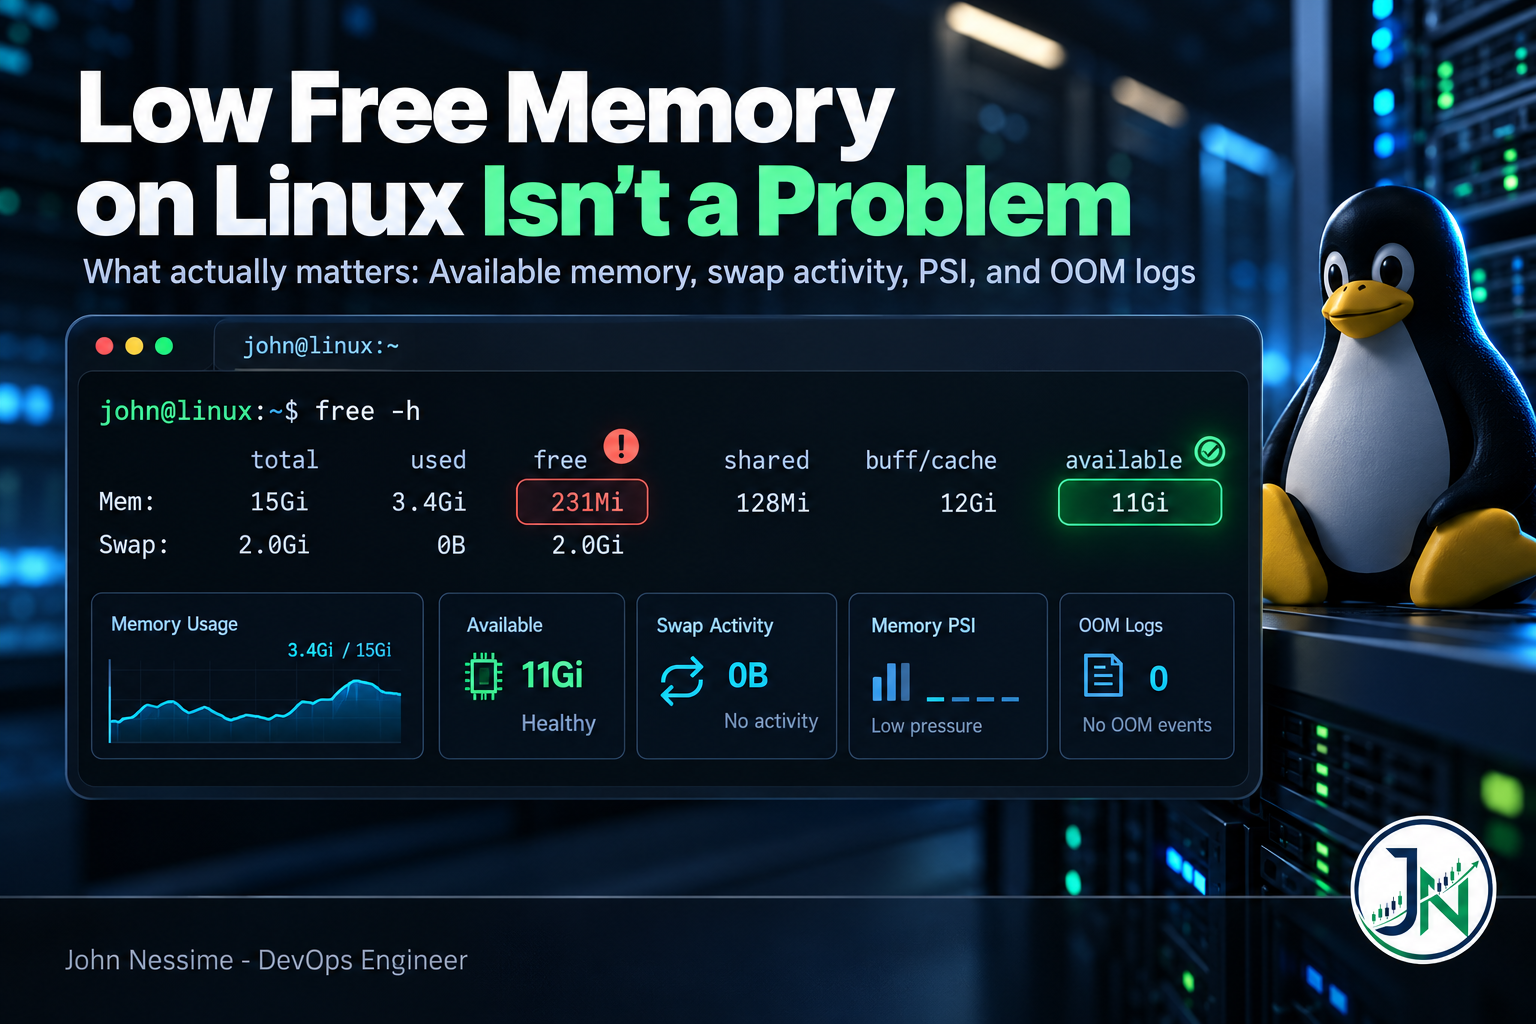
The ticket came in flagged as urgent. A screenshot was attached: free -h on a database server, showing a little over 200 MB in the free column on a machine with 16 GB of RAM. Somebody had already drafted a change request to double the instance size before anyone looked at the rest of the output.
The same output showed roughly 11 GB in the available column. Nothing was wrong, and nothing had been wrong for months. The only thing broken was the alert that fired.
Low free memory on Linux is one of the most reliably misread signals in server operations. It looks like an emergency, it triggers scaling decisions, and it is almost always noise. This post covers what free is really telling you, which four signals actually indicate memory trouble, the one situation where a low free number genuinely matters, and what to put in your alert rules instead.
What the free command is actually reporting
free does not measure anything. It parses /proc/meminfo and prints a handful of those fields in columns. Every number it shows comes straight from the kernel and is readable directly if you want to skip the formatting.
A typical reading on a busy server looks roughly like this:
$ free -h
               total        used        free      shared  buff/cache   available
Mem:            15Gi       3.4Gi       231Mi       128Mi        12Gi        11Gi
Swap:          2.0Gi          0B       2.0Gi
Read that left to right and the story is boring. Applications hold a few gigabytes. The kernel filled almost everything else with page cache and buffers, because every file that gets read or written passes through memory on the way, and directory metadata lands in reclaimable slab. What is left over, genuinely untouched, is the free column.
That last part is the bit people miss. Free memory is not a reserve. It is waste. A page holding a cached copy of a file your application reads every few seconds is doing useful work. A page sitting empty is doing nothing, and the kernel converts it into cache the moment it has a reason to. A server that has been up for a week and still shows plenty of free memory is a server that is barely touching its disk.
If you want the raw source rather than the formatted view:
$ grep -E '^(MemTotal|MemFree|MemAvailable|Buffers|Cached|SReclaimable|SwapTotal|SwapFree|Dirty):' /proc/meminfoTwo options are worth knowing. free -w switches to wide mode and splits buffers and cache into separate columns, which helps when attributing memory to a specific I/O pattern. free -h -s 5 reprints every five seconds, a crude but effective trend view while you reproduce a problem.
Signal one: available memory, not free memory
The available column maps to MemAvailable in /proc/meminfo, and it is the kernel’s own estimate of how much memory a new workload could allocate without pushing the system into swap. It has been present since kernel 3.14, so every distribution you are likely to be running exposes it.
What matters is that it is not free plus cache. That naive sum is what people calculated before MemAvailable existed, and it overstates the truth. The kernel starts from free pages, subtracts the reserves it refuses to dip below, then adds back the portion of file-backed page cache and reclaimable slab it believes it could actually release. Both additions are capped, because some cache is pinned and some reclaimable slab objects are in use.
The kernel documentation is explicit that this is an estimate whose accuracy varies from system to system, so treat it as a strong hint rather than an exact figure. It is still far better than anything you can compute yourself, and it is the number your dashboards should be built on.
If you change one thing after reading this: point your memory alerts at available, not at free. Everything else in this post is refinement on top of that.
Signal two: swap activity, not swap usage
The second most common false alarm is swap. Someone sees a few hundred megabytes of swap in use and concludes the machine is thrashing. It usually isn’t.
Swap usage is a stock: pages moved to disk at some point, possibly during a backup weeks ago, and never needed since. Leaving them there is correct, and pulling them back to satisfy a dashboard would evict something useful. Swap activity is a flow, and that is the part that hurts, because a page fault serviced from disk is orders of magnitude slower than one serviced from RAM.
vmstat gives you the flow. The si and so columns are swap-in and swap-out, in blocks per second over the sampling interval:
$ vmstat 5 6Discard the first row. vmstat reports averages since boot on its first line, which is almost never what you want. Read the rows after that. If si and so are both consistently non-zero, the machine is simultaneously reading pages back to serve current work and writing pages out to make room for new allocations. That is thrashing, and it is a real signal with no ambiguity attached.
A single non-zero sample is not that. Brief swap activity during a log rotation or a backup window is normal. Sustained activity across several consecutive samples is what to escalate.
Signal three: memory pressure, which is the one that catches things early
Pressure Stall Information is the signal I reach for first now, and it is badly underused. It has been in the kernel since 4.20 and it answers a question none of the other tools answer directly: how much time are my processes losing because memory is contended?
$ cat /proc/pressure/memory
some avg10=0.00 avg60=0.00 avg300=0.00 total=0
full avg10=0.00 avg60=0.00 avg300=0.00 total=0
The some line is the share of wall-clock time in which at least one task was stalled waiting on memory. The full line is the share in which every non-idle task was stalled, meaning nothing useful happened at all. The averages cover ten seconds, one minute and five minutes, and total is a cumulative counter in microseconds that updates continuously, so it catches a two-second stall the running averages smooth away entirely.
Here is why this beats a percentage threshold. Utilization tells you how much of a resource is consumed; pressure tells you whether that consumption is costing you anything. A machine can sit at high utilization for months with zero pressure, which means the sizing is fine. It can also sit at moderate utilization while full climbs, which means reclaim is working hard and latency is already suffering with no threshold crossed.
With cgroup v2 mounted, the same data exists per cgroup in each directory’s memory.pressure file, so you can attribute pressure to a specific service rather than the whole machine. Prometheus node_exporter collects the system-level PSI counters, and if you already ship metrics to something like Grafana Cloud these graph well beside your latency panels.
Signal four: the OOM log, which is the only unambiguous one
When memory really does run out, the kernel writes a record. It does not do this quietly and it does not do it conditionally. If there is no OOM record, no process was killed for memory, full stop.
$ sudo journalctl -k --since "24 hours ago" | grep -i "oom"
$ sudo dmesg -T | grep -i "killed process"
The kill line names the victim and reports its memory breakdown at the moment of death: total virtual size, anonymous resident set, file-backed resident set, shared memory resident set, and the oom_score_adj that was in effect. The line above it, where a process “invoked oom-killer”, tells you which allocation triggered the whole event, and that process is frequently not the one that got killed.
That distinction is the most useful thing in the log. The kernel picks a victim by badness score, driven largely by how much memory a process holds relative to what is available to it, adjusted by oom_score_adj. A slow leak in a small helper can push the machine over the edge and get your database killed instead, because the database is simply the largest thing running. Read both lines before deciding who the culprit is.
If you have a service that should survive at almost any cost, systemd exposes OOMScoreAdjust= in the unit file, which persists across restarts in a way that writing to /proc/<pid>/oom_score_adj does not. Use it sparingly. Protecting a process that is itself leaking just moves the crash somewhere less convenient.
When low free memory on Linux really is the problem
Everything above assumes you are looking at a whole machine. Inside a container, the accounting changes, and this is the failure mode that is invisible until it isn’t.
The cgroup memory controller charges page cache to the cgroup that caused it. Clean, evictable, perfectly reclaimable cache still counts toward memory.current, and that is what gets compared against memory.max. A container reading a large file has just charged that file to its own budget.
$ cat /sys/fs/cgroup/memory.current
$ cat /sys/fs/cgroup/memory.max
$ grep -E '^(anon|file|slab_reclaimable) ' /sys/fs/cgroup/memory.stat
The split in memory.stat is what you actually want. anon is memory your process genuinely holds; file is page cache charged to you that the kernel can take back under pressure. A container at its limit on mostly file is in a very different position from one at its limit on mostly anon.
Two things follow from this that catch people out repeatedly:
- Reclaim is not instant. Under heavy pressure the reclaim path itself runs slowly, so a container can be OOM-killed while still holding clean page cache that was theoretically available.
- Running
freeinside a container lies to you. Unless something virtualizes/proc, you are reading the host’s/proc/meminfo, which knows nothing about your limit. The cgroup files are the only truth here.
cgroup v2 also has memory.high, a soft limit. Crossing it triggers reclaim and throttling rather than a kill, which turns a hard failure into a slow one. That is usually the better trade, and it is worth setting deliberately rather than leaving it at its default.
What to alert on
The alert on the ticket at the top of this post was watching the wrong number. Here is what a memory alert set looks like when it watches the right ones:
- Available memory below a percentage of total, sustained. Ten percent for ten minutes is a reasonable starting shape. A single thirty-second dip is noise and should never page anyone.
- Sustained swap-in and swap-out together. Rate of change on the swap counters, not the absolute amount of swap in use.
- Memory PSI rising. The
someline moving off the floor is your early warning. Thefullline moving at all is your late one. - Any OOM kill, ever. This one is binary and should always generate a ticket, even if the service recovered on its own.
- Per-container memory events. The cgroup
memory.eventsfile counts limit hits, and a rising count is a limit that needs revisiting.
Notice that free memory does not appear anywhere in that list. There is no threshold on the free column that produces a useful alert, because the number is a byproduct of the kernel’s caching behaviour rather than a measure of anything you care about.
Troubleshooting: which tool answers which question
When a memory question lands on you, the order you check things in matters more than the tools.
- Did anything actually die? Check the kernel log for OOM records first. If there are none, this is a performance question and not a capacity failure, which changes everything about what you do next.
- Is the machine stalling? Read
/proc/pressure/memory. Zero pressure with low free memory means you are done. Go close the ticket. - Is it swapping right now? Run
vmstat 5for half a minute and watchsiandso. Ignore the first row. - Who is holding the memory?
ps aux --sort=-%mem | head -15gets the shortlist. Resident set size double-counts shared pages, so summing the column overstates the total. - Is it the kernel rather than a process? If the process list does not account for the usage, check
slabtopandSUnreclaimin/proc/meminfo. Unreclaimable slab growth is a different problem, usually a driver, filesystem or network workload creating enormous numbers of kernel objects. - Is it growing? A leak is a slope, not a level, and one reading tells you nothing. This is the whole argument for having the graph before you need it.
One more that saves time on crowded boxes: resident set size is the wrong measure of what a process really costs, because shared libraries are counted against every process that maps them. Proportional set size divides shared pages among the processes sharing them, and tools reporting PSS give a far more honest answer when you are deciding what to move off a busy VPS.
Common mistakes
- Dropping caches to make the number look better. Writing to
/proc/sys/vm/drop_cachesdiscards clean page cache and reclaimable slab. The kernel documentation says plainly that using it outside testing or debugging is not recommended, because everything dropped has to be re-read from disk. You trade a nicer-lookingfreeoutput for an I/O spike and worse latency. It is a benchmarking tool, not an operations tool. - Setting
vm.swappinessto zero as a reflex. It does not disable swap and it does not make the machine faster. It makes the kernel strongly prefer evicting page cache over swapping anonymous pages, which on a database host means throwing away exactly the cache you wanted. Change it for a measured reason, not by default. - Running with no swap at all. Swap is not just an overflow area. Without it the kernel loses the option of paging out genuinely cold anonymous memory, which means the only lever left under pressure is evicting cache or killing something. A modest swap file gives reclaim somewhere to go.
- Summing RSS across processes and comparing it to total RAM. Shared pages are counted once per process. The sum will exceed reality, sometimes dramatically.
- Resizing the instance before finding the slope. More RAM buys time against a leak. It does not fix one, and the bill arrives every month afterwards.
Best practices
- Graph available memory, swap rate and memory PSI on one panel. Together they read as a story; individually each one misleads.
- Keep the raw counters, not just derived percentages. A percentage of an instance size that has since changed cannot answer “was this happening last week”.
- Set container limits from observed
anonusage plus headroom, not a round number someone picked, and putmemory.highbelowmemory.maxso pressure shows up as slowness before it shows up as a kill. - Alert on rate of change for anything that can leak. The steady climb is the signal; the level it reached is just when you happened to look.
- Right-size deliberately. On providers such as Contabo or InterServer, where RAM is a meaningful share of the monthly bill, the gap between a real requirement and a panicked upgrade is money you keep every month.
- Write the explanation down where your team will find it. Every organization rediscovers the free-versus-available confusion independently, usually at three in the morning.
Frequently asked questions
Why is free memory so low on my Linux server?
Because the kernel used it for page cache and buffers, which is the intended behaviour. Any file read or written passes through memory, and the kernel keeps those pages in case they are needed again. It reclaims them automatically the moment an application needs the space. Check the available column instead.
What is the difference between free and available in free -h?
Free is memory that is completely unused. Available is the kernel’s estimate of how much a new process could allocate without swapping: free memory plus the portion of cache and reclaimable slab it believes it could release. Available is almost always much larger, and it answers the question you are actually asking.
Should I clear the page cache to free up memory?
No. The kernel reclaims cache automatically under pressure, and more selectively than a blanket drop. Writing to drop_caches forces everything to be re-read from disk, and the kernel documentation advises against using it outside testing or debugging. Doing it on a schedule is a strong hint something else is misconfigured.
Is swap being used a bad sign?
Not by itself. Pages that were swapped out during a quiet period and never needed again are fine where they are. What matters is swap traffic: sustained non-zero si and so in vmstat at the same time means the machine is thrashing. Alert on the rate, not the amount.
How do I tell if a process was killed for running out of memory?
Search the kernel log. journalctl -k filtered for “oom”, or dmesg -T filtered for “killed process”, shows a record naming the process, its PID and its memory breakdown at the time. The kernel always logs this, so if there is no record the process died for some other reason.
Why does my container get OOM-killed when memory looks fine inside it?
Because free inside a container usually reads the host’s memory information, not the cgroup limit being enforced. Read memory.current, memory.max and memory.stat instead. Page cache charged to the container counts toward its limit, so a read-heavy workload can hit the ceiling without any process holding much anonymous memory.
What is a good memory alert threshold?
Available memory below roughly ten percent of total, sustained for ten minutes, is a defensible starting point to tune against your own workload. Pair it with memory PSI and an unconditional alert on any OOM kill. A threshold on the free column, at any value, will page you for nothing.
Conclusion
Low free memory on Linux is the expected steady state of a healthy, working server. The kernel fills memory with cache because empty memory earns nothing, and hands it back the instant an application asks. The free column is a byproduct of that behaviour, not a health metric, and alerting on it produces exactly the kind of urgent ticket that wastes an afternoon and ends in a change request nobody needed.
The one thing worth remembering: free tells you what is idle, available tells you what you can have, and pressure tells you whether any of it is costing you. Watch the second and third, log the OOM events, and read the cgroup files rather than free whenever a container is involved.
Need help reading your memory signals?
Most of the memory work I get asked for is not “add more RAM”. It is working out whether the number someone is worried about means anything. I can help with:
- Rebuilding memory alerts around available memory, swap rate and PSI so they stop paging on normal cache behaviour
- Diagnosing repeated OOM kills, including the cases where the process being killed is not the one causing the problem
- Setting container and pod memory limits from observed anonymous usage rather than guesses, with a soft limit so pressure surfaces before a kill does
- Separating a genuine leak from normal cache growth using retained metrics rather than a single reading
- Right-sizing servers and instances honestly, up or down, based on what the workload actually needs
- Building the dashboard that turns the next memory question into a five-minute conversation instead of an incident
If you have a free -h output, a vmstat capture or an OOM log line that is bothering you, send it over and I will tell you what it means.