Customer Sentiment Analysis From CRM and Support Data: Building a Score You Can Actually Trust

Most customer sentiment analysis pipelines run perfectly and still produce a number nobody should act on. Here are the failure families that cause it, from labels stamped on the wrong message to averages taken over a scale that was never numeric, plus a pipeline shape and a legal boundary worth knowing before you ship.
Continue ReadingCustomer Sentiment Analysis From CRM and Support Data: Building a Score You Can Actually Trust

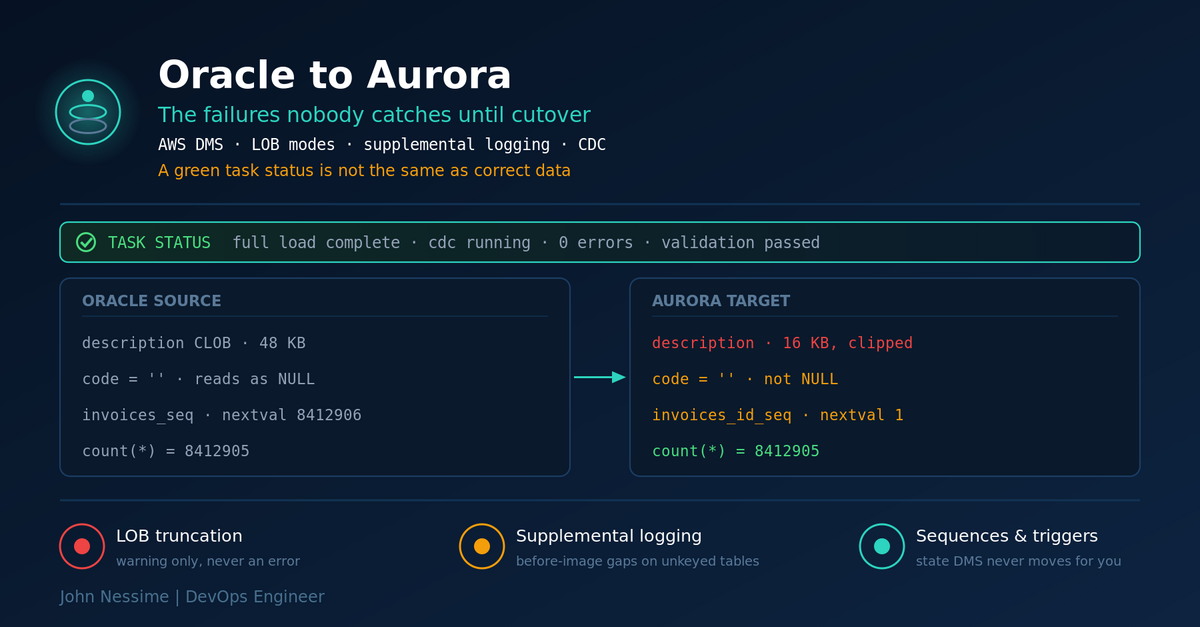
Oracle to Aurora Migration: The Failures Nobody Catches Until Cutover

Most Oracle to Aurora migrations don't fail loudly. They finish green, pass validation, and quietly hand you truncated LOBs, sequences stuck at 1, and empty strings that used to be NULL. Here are the four failure families to check before you cut over, with the SQL and task settings that catch them.

Continue ReadingOracle to Aurora Migration: The Failures Nobody Catches Until Cutover

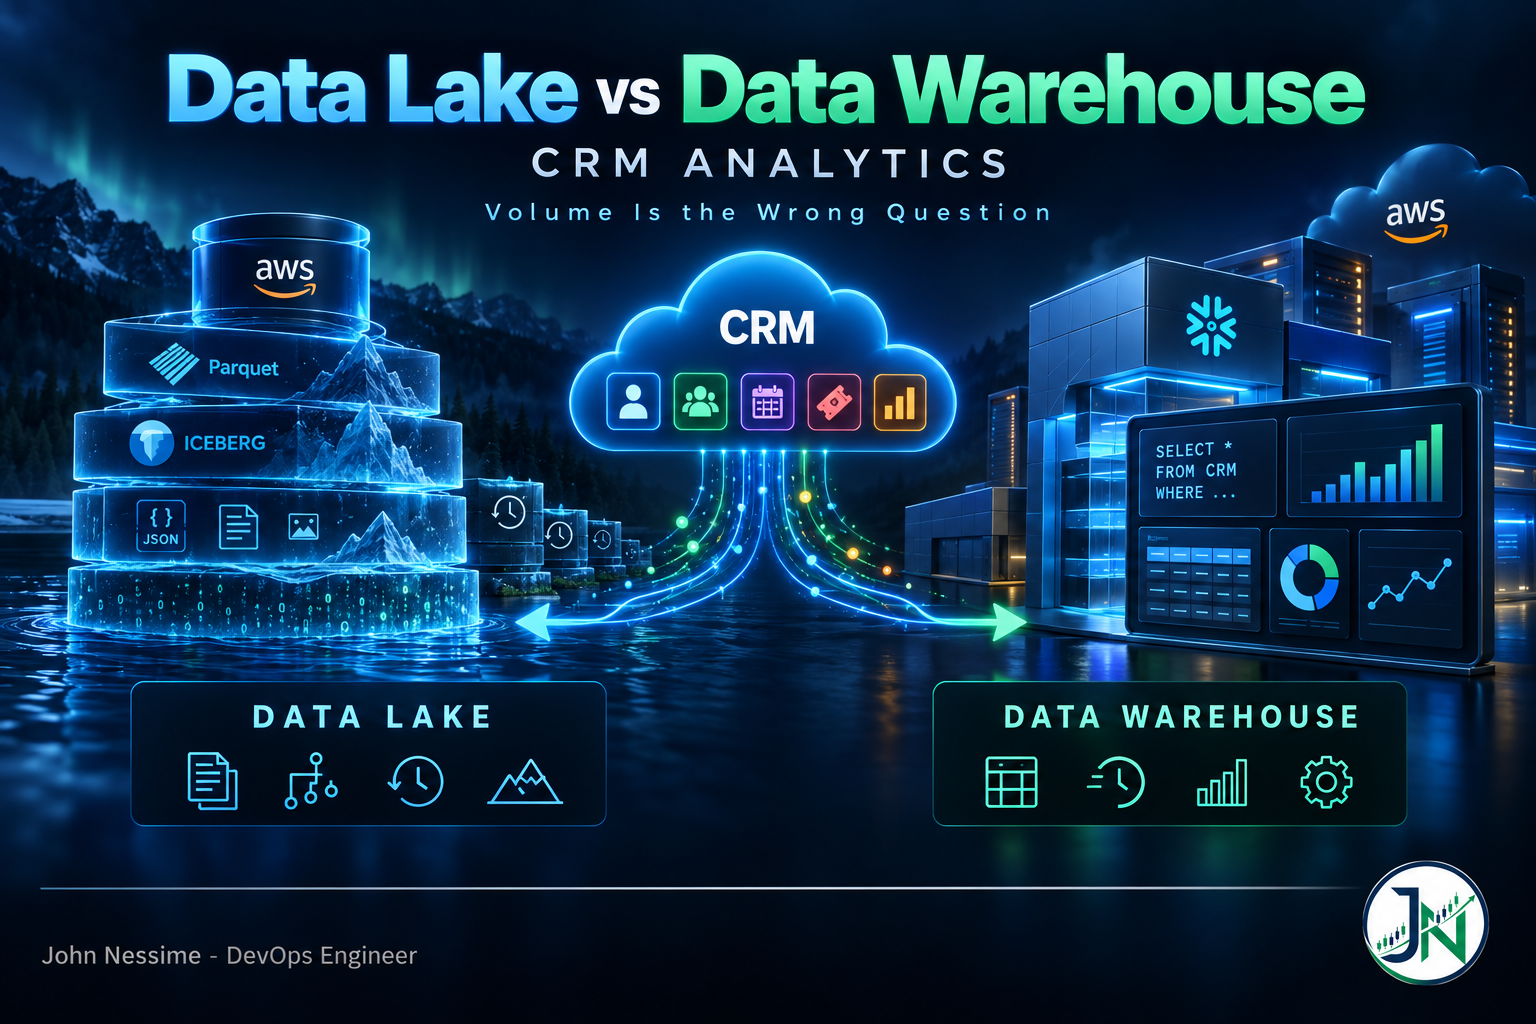
Data Lake vs Data Warehouse for CRM Analytics: Volume Is the Wrong Question

Everyone argues this one on data volume, and volume is the argument that matters least: CRM data is small enough that both architectures handle it comfortably. What actually decides data lake vs data warehouse for CRM analytics is how much point-in-time history you need, how fast the schema churns, what shape your queries are, and who is going to maintain the thing. Includes a decision procedure you can run in an afternoon.

Continue ReadingData Lake vs Data Warehouse for CRM Analytics: Volume Is the Wrong Question

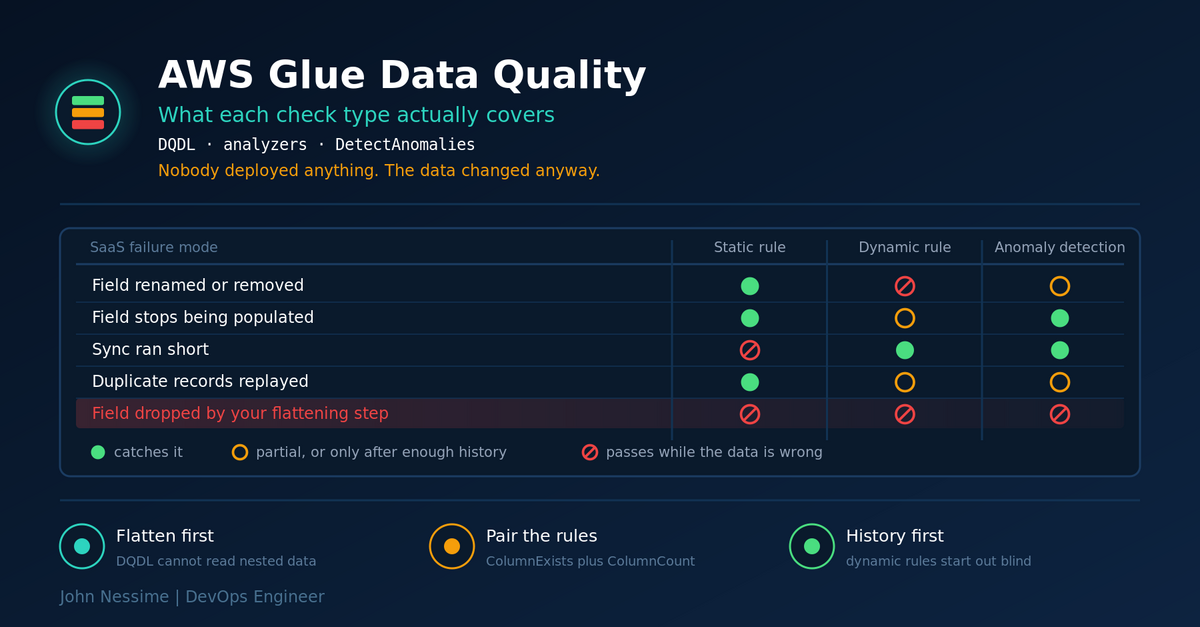
AWS Glue Data Quality for SaaS Data: Catching the Breakage Nobody Deployed

A SaaS admin changes a field and your pipeline stays green while the numbers drift. A practical guide to AWS Glue Data Quality for SaaS sources: where to run the checks, why nested payloads need flattening before DQDL can see them, which rule catches which failure, and the dynamic rules that pass silently because they have no history yet.

Continue ReadingAWS Glue Data Quality for SaaS Data: Catching the Breakage Nobody Deployed

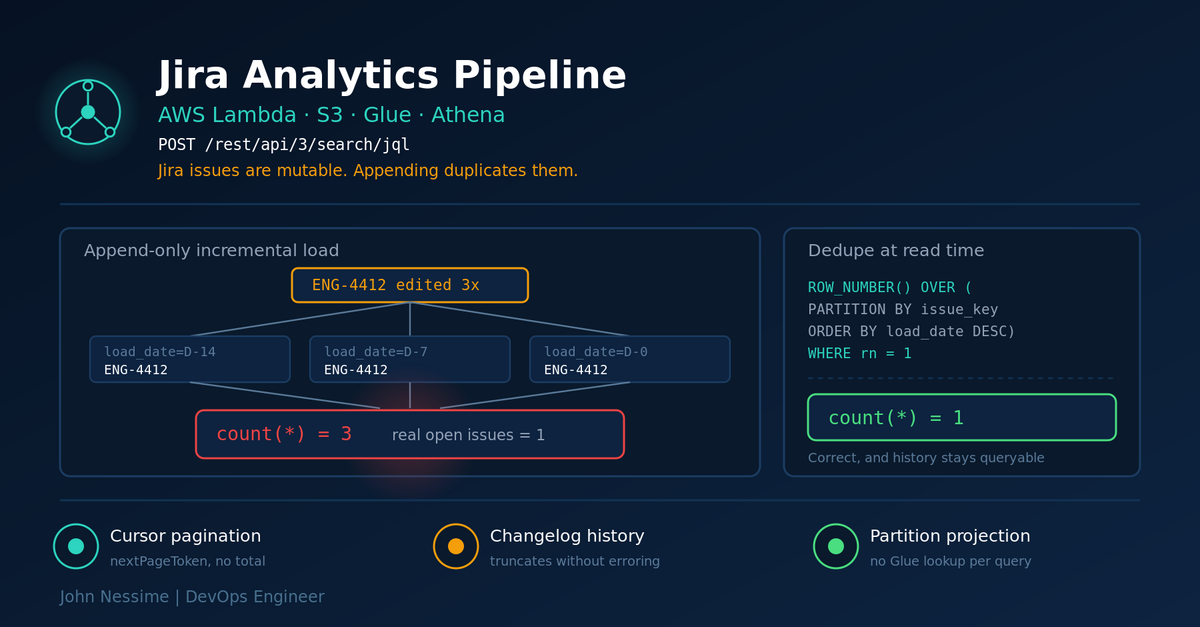
Building a Jira Analytics Pipeline with AWS Lambda and Athena (Without Double-Counting Everything)

Jira's built-in reports stop at the board boundary. This guide walks through a Jira analytics pipeline built on AWS Lambda, S3 and Athena, organised around the four failure families that actually bite: the removed search endpoint, silently truncated changelogs, incremental loads that duplicate rows, and an S3 layout that quietly inflates your query bill.

Continue ReadingBuilding a Jira Analytics Pipeline with AWS Lambda and Athena (Without Double-Counting Everything)

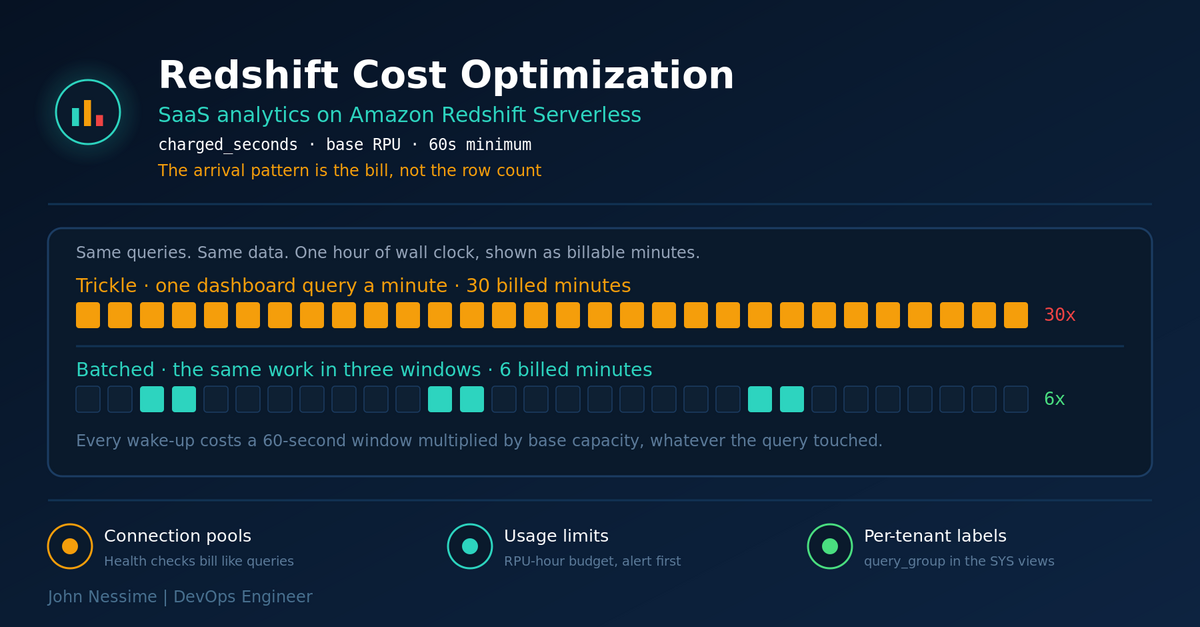
Redshift Cost Optimization for SaaS Analytics: The Levers That Actually Move the Bill

In a SaaS analytics product, the Redshift bill tracks how often queries arrive, not how much data they touch. Here is how the meter actually works, why connection pools bill you while nobody is using the product, how to attribute spend to a tenant, and which isolation choices quietly cost more than they save.

Continue ReadingRedshift Cost Optimization for SaaS Analytics: The Levers That Actually Move the Bill