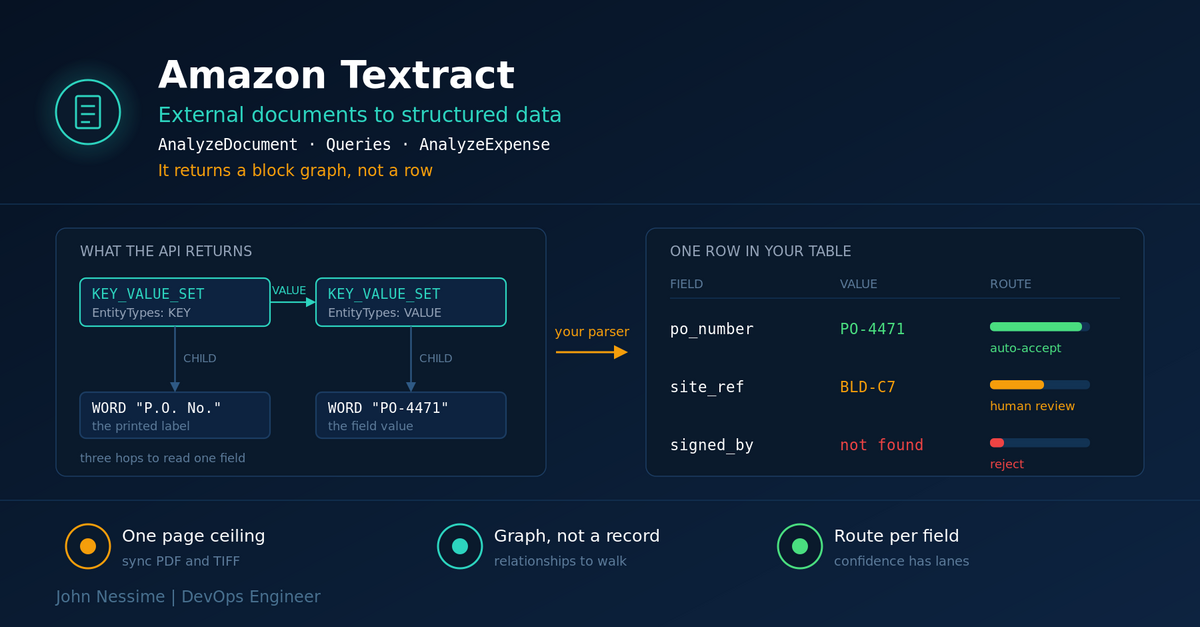
Turning External Documents Into Structured Data With Amazon Textract

Amazon Textract almost never fails loudly. A working guide to turning external PDFs and scans into structured data: picking the right operation per document family, parsing the block graph, routing on per-field confidence, and catching the limits that silently truncate your records.
Continue ReadingTurning External Documents Into Structured Data With Amazon Textract

Backfilling Historical API Data into S3 Without Silent Gaps

A backfill that exits zero can still be missing a week of data, and nothing will tell you. This is a practical guide to the failure families behind silent gaps: pagination drift under a mutating source, retries that duplicate pages, prefix layouts designed for writes instead of reads, the seam where backfill meets live ingest, and the storage class rules that make mistakes expensive. Includes deterministic key derivation, S3 conditional writes, Athena partition projection, and a per-window manifest pattern that turns completeness into something you can query.

Continue ReadingBackfilling Historical API Data into S3 Without Silent Gaps

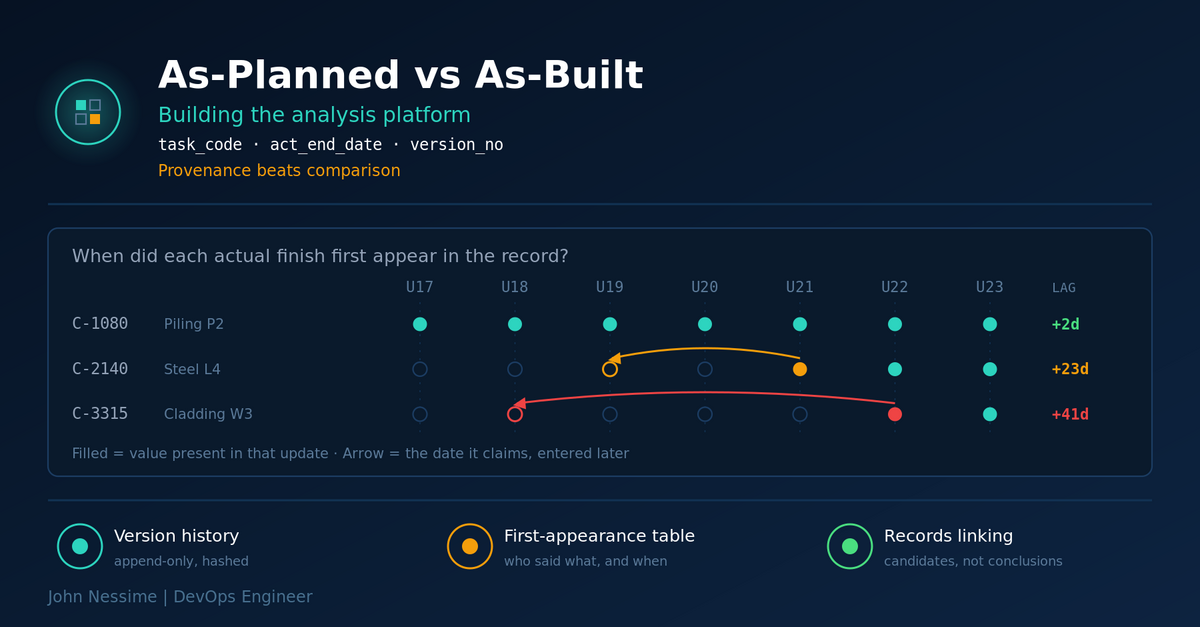
As-Planned vs As-Built Analysis: Building a Platform That Survives Cross-Examination

Most as-planned vs as-built analysis compares the baseline to the last P6 update and calls the result an as-built. It isn't one. This is how to build the data layer underneath a delay analysis: versioned XER ingestion, activity identity across renumbering, a first-appearance table that proves when every actual date entered the record, calendar-safe float, and record linking that proposes candidates instead of asserting cause.

Continue ReadingAs-Planned vs As-Built Analysis: Building a Platform That Survives Cross-Examination

Customer Sentiment Analysis From CRM and Support Data: Building a Score You Can Actually Trust

Most customer sentiment analysis pipelines run perfectly and still produce a number nobody should act on. Here are the failure families that cause it, from labels stamped on the wrong message to averages taken over a scale that was never numeric, plus a pipeline shape and a legal boundary worth knowing before you ship.

Continue ReadingCustomer Sentiment Analysis From CRM and Support Data: Building a Score You Can Actually Trust

Amazon Textract Data Extraction: What Breaks on Real Contracts and Reports

Textract rarely fails loudly. It returns a plausible result that is quietly incomplete: a truncated result set, a tick box read as an empty string, a clause split across a page break. A practitioner's guide to the failure modes that actually bite when you point Amazon Textract at contracts, technical reports and correspondence, plus how to choose between sync and async, which feature types are worth paying for, and where Textract stops being the right tool.

Continue ReadingAmazon Textract Data Extraction: What Breaks on Real Contracts and Reports

Apache Airflow on AWS: Building SaaS and API Pipelines That Don’t Lie to You

Most API pipeline failures are green DAGs producing incomplete data. A practical guide to running Apache Airflow on AWS for SaaS and API extraction: choosing between MWAA provisioned, MWAA Serverless and self-managed, the pool setting that silently stops throttling when you go deferrable, retry and pagination design, secrets handling, and the four cost lines that actually move.

Continue ReadingApache Airflow on AWS: Building SaaS and API Pipelines That Don’t Lie to You

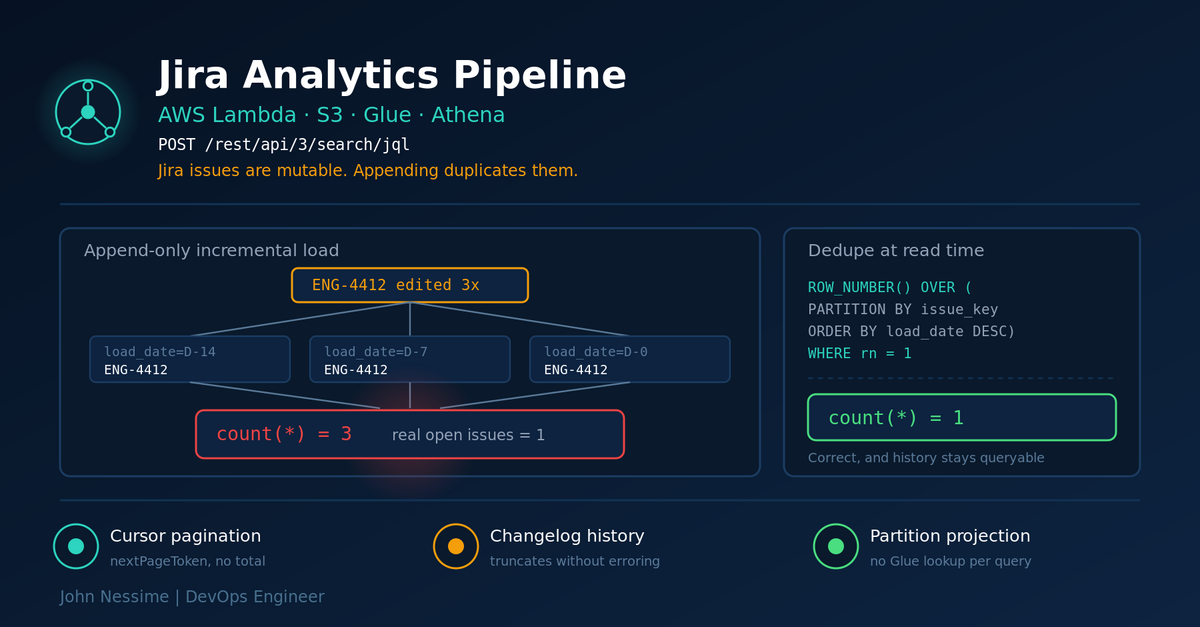
Building a Jira Analytics Pipeline with AWS Lambda and Athena (Without Double-Counting Everything)

Jira's built-in reports stop at the board boundary. This guide walks through a Jira analytics pipeline built on AWS Lambda, S3 and Athena, organised around the four failure families that actually bite: the removed search endpoint, silently truncated changelogs, incremental loads that duplicate rows, and an S3 layout that quietly inflates your query bill.

Continue ReadingBuilding a Jira Analytics Pipeline with AWS Lambda and Athena (Without Double-Counting Everything)

Run It Twice, Get Two Answers: Building an ETL Pipeline From Zoho CRM to Amazon S3

You re-run the same extract for the same window and get a different set of rows. Nothing errored. You were paginating a result set that kept changing while you read it. Here's how to build a Zoho CRM to S3 pipeline whose runs are repeatable, from closed read windows to Bulk Read and deletions.

Continue ReadingRun It Twice, Get Two Answers: Building an ETL Pipeline From Zoho CRM to Amazon S3