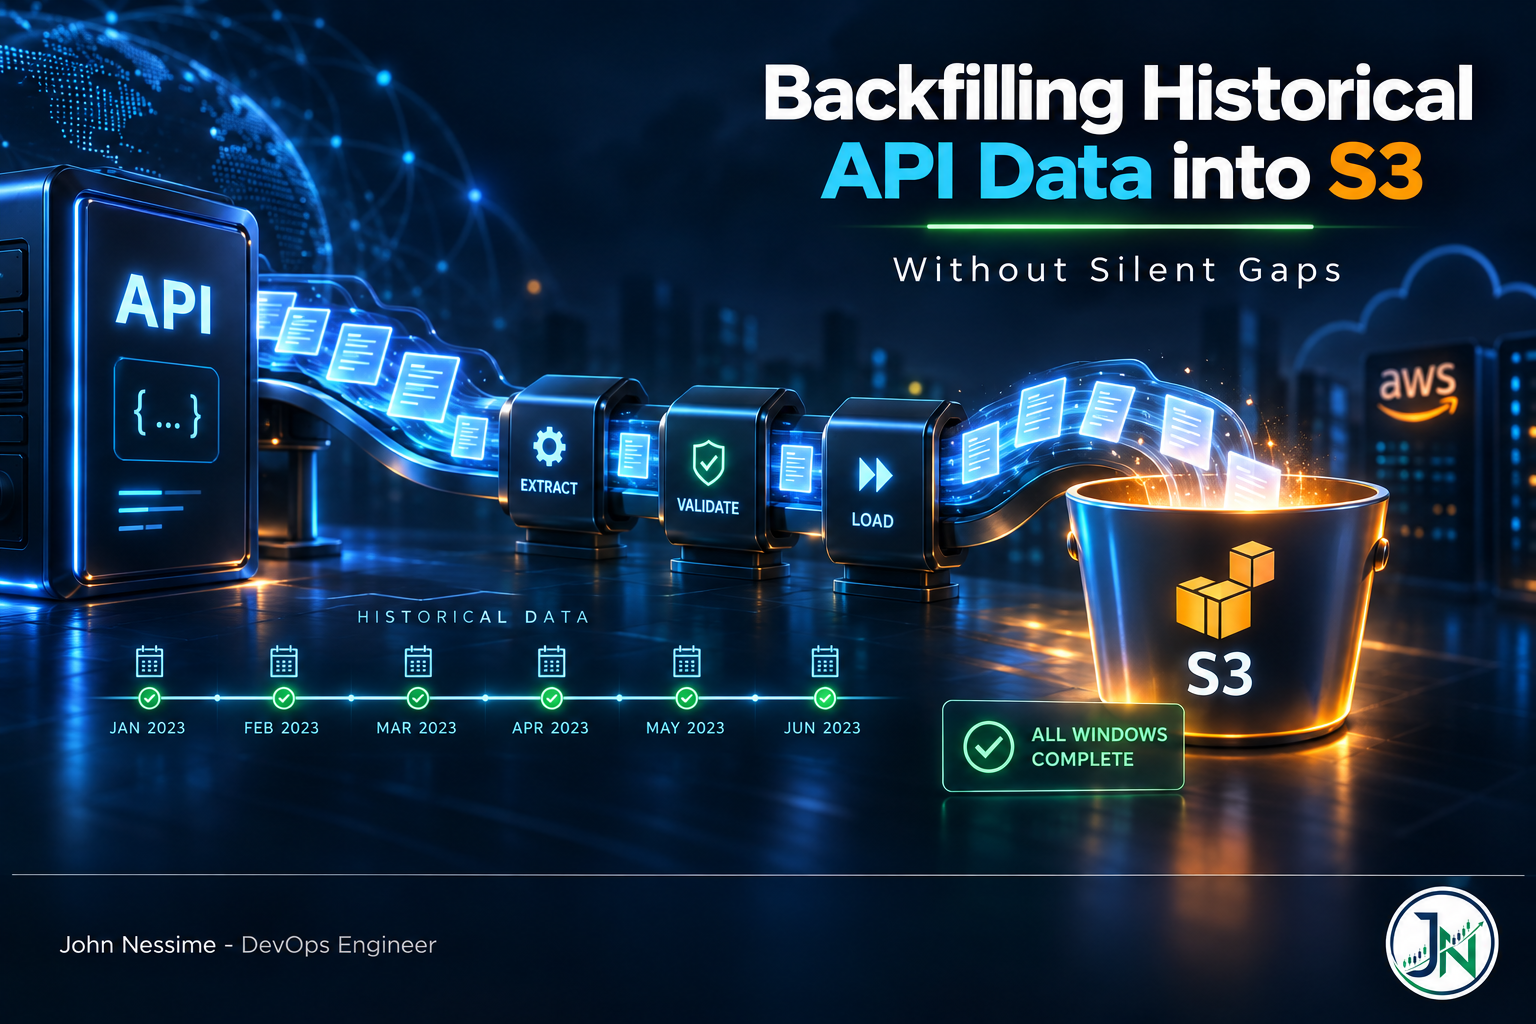
Backfilling Historical API Data into S3 Without Silent Gaps

A backfill that exits zero can still be missing a week of data, and nothing will tell you. This is a practical guide to the failure families behind silent gaps: pagination drift under a mutating source, retries that duplicate pages, prefix layouts designed for writes instead of reads, the seam where backfill meets live ingest, and the storage class rules that make mistakes expensive. Includes deterministic key derivation, S3 conditional writes, Athena partition projection, and a per-window manifest pattern that turns completeness into something you can query.

Continue ReadingBackfilling Historical API Data into S3 Without Silent Gaps

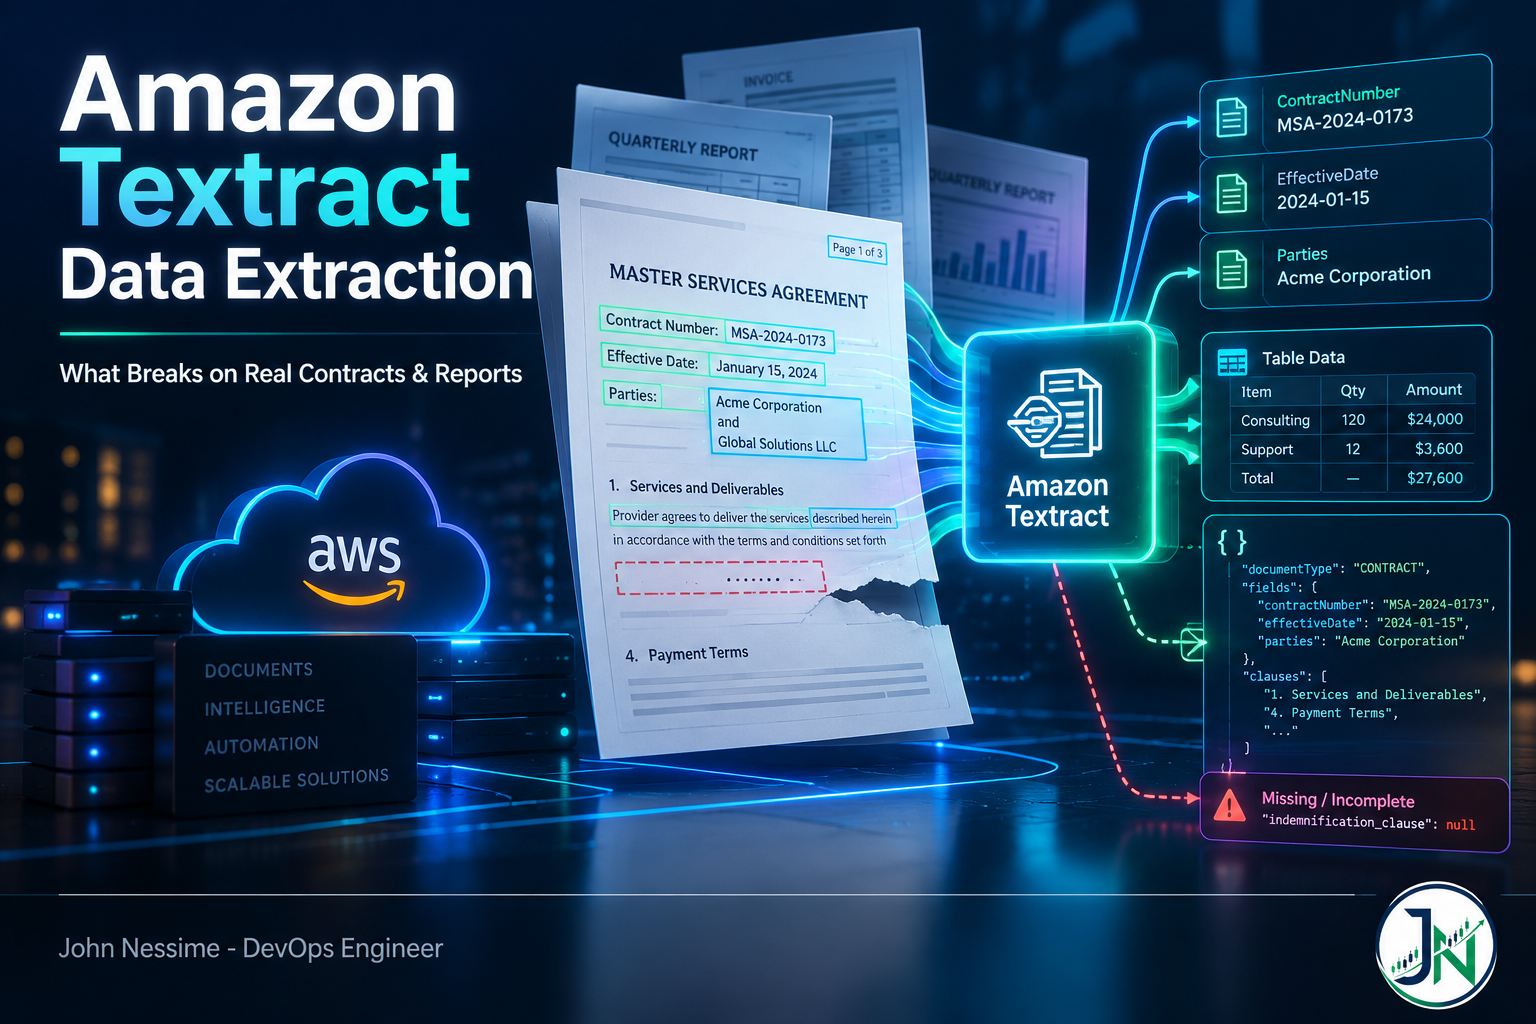
Amazon Textract Data Extraction: What Breaks on Real Contracts and Reports

Textract rarely fails loudly. It returns a plausible result that is quietly incomplete: a truncated result set, a tick box read as an empty string, a clause split across a page break. A practitioner's guide to the failure modes that actually bite when you point Amazon Textract at contracts, technical reports and correspondence, plus how to choose between sync and async, which feature types are worth paying for, and where Textract stops being the right tool.

Continue ReadingAmazon Textract Data Extraction: What Breaks on Real Contracts and Reports

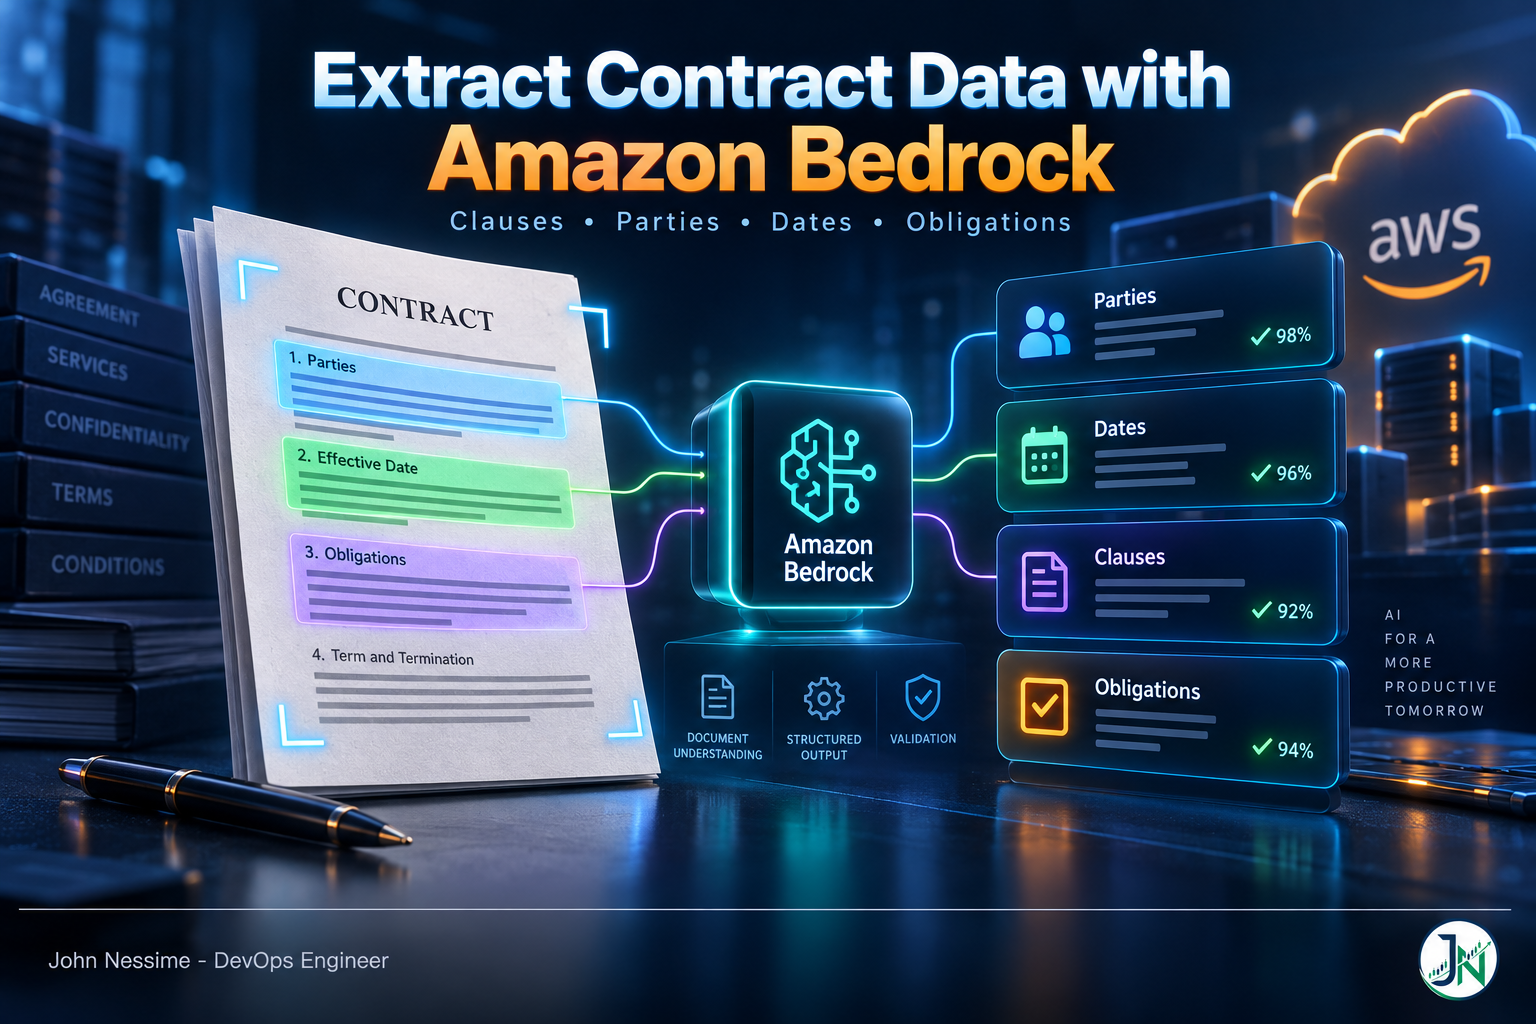
Extracting Clauses, Parties, Dates and Obligations with Amazon Bedrock

Valid JSON is not correct data. A practical guide to extracting clauses, parties, dates and obligations from contracts with Amazon Bedrock: the two build paths, schema design, the three failure families that produce confident wrong answers, and the validation layer that catches them.

Continue ReadingExtracting Clauses, Parties, Dates and Obligations with Amazon Bedrock

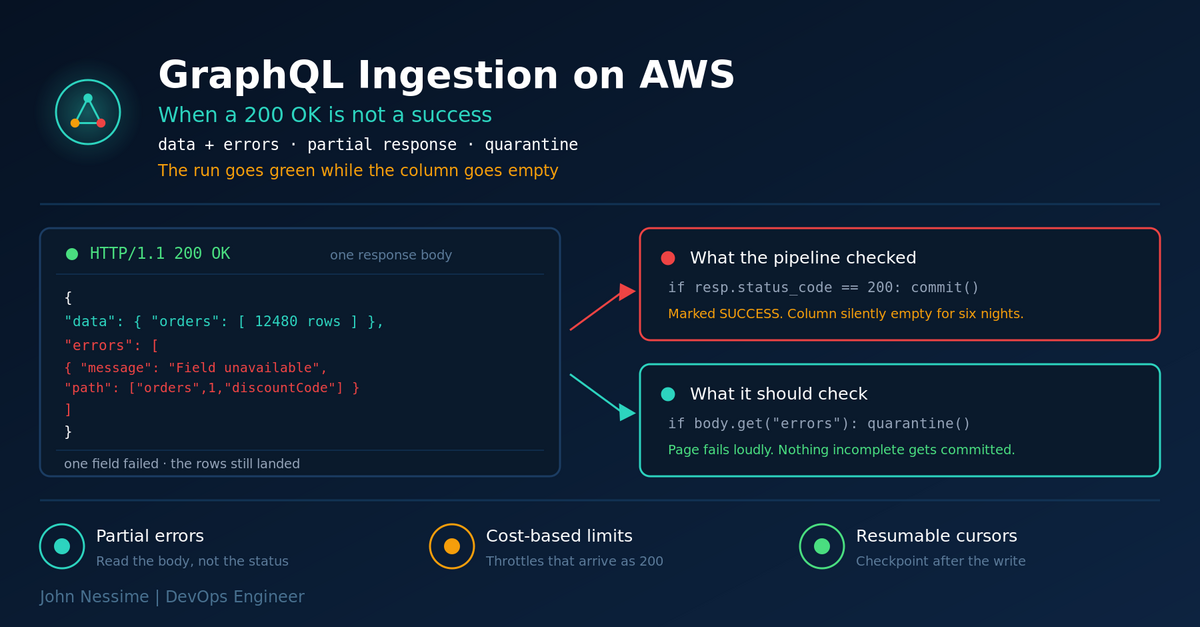
Building a GraphQL Data Ingestion Pipeline on AWS That Doesn’t Lie to You

A GraphQL source can hand you a 200 OK, a populated data block, and a quietly broken column in the same response. Here is how to build a GraphQL data ingestion pipeline on AWS that catches partial errors, respects cost-based rate limits, resumes cleanly from a cursor, and notices when the schema moves under you.

Continue ReadingBuilding a GraphQL Data Ingestion Pipeline on AWS That Doesn’t Lie to You

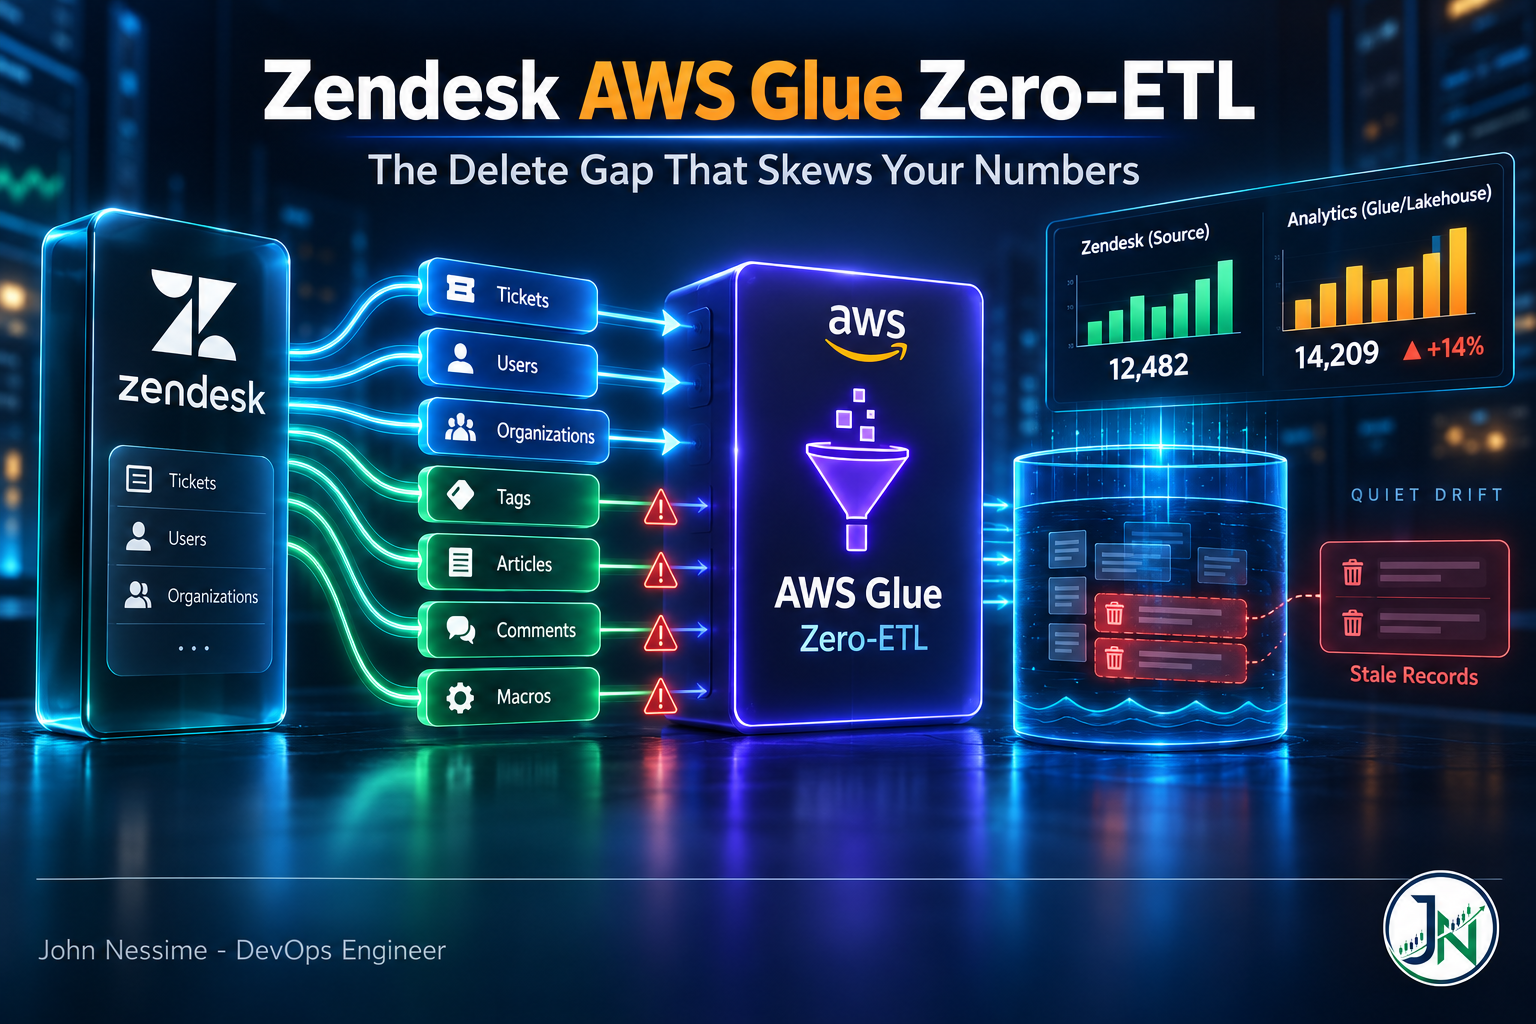
Zendesk Data Integration with AWS Glue Zero-ETL: The Delete Gap That Skews Your Numbers

AWS Glue zero-ETL replicates seven Zendesk entities, but only three of them ever remove a row. Here is how that gap quietly skews CSAT and knowledge base counts, plus the three IAM layers to wire, the two settings you cannot change after creation, and the CloudWatch metrics that make drift visible before someone spots it in a meeting.

Continue ReadingZendesk Data Integration with AWS Glue Zero-ETL: The Delete Gap That Skews Your Numbers