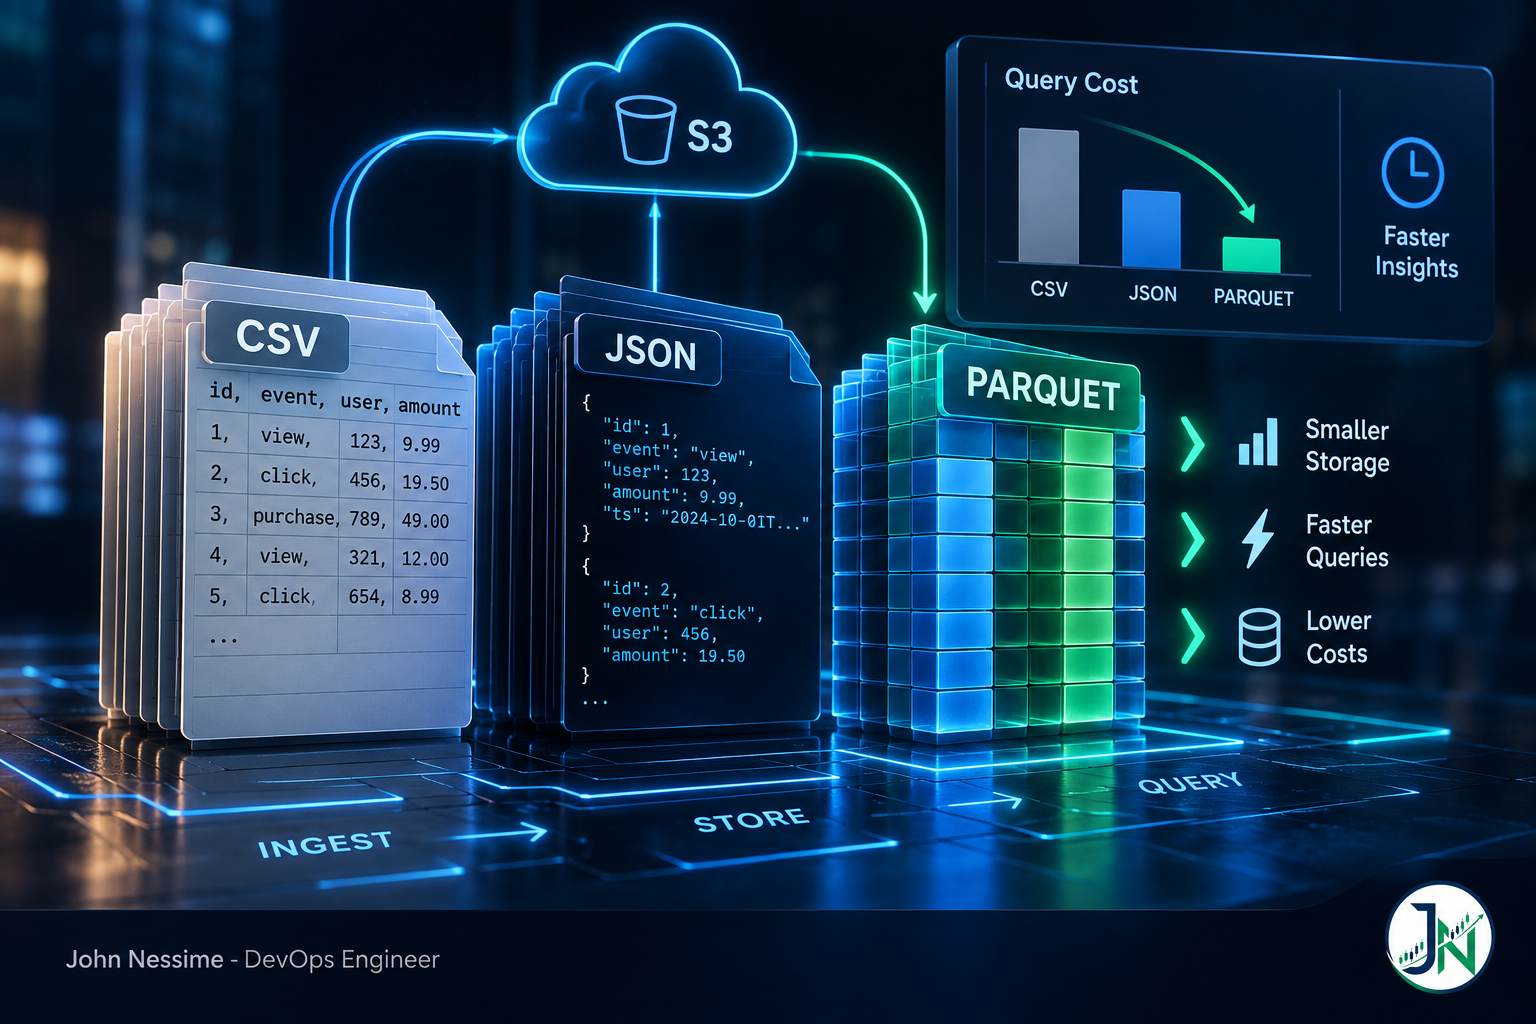
Building a Hotel Data Lake on AWS That Agrees With the Night Audit

Hotel source data is mutable in the past, so an append-only pipeline drifts away from the PMS without anyone noticing until month close. A practical guide to room-night grain, bitemporal modeling with Apache Iceberg, PMS ingestion, guest data scope, and file physics at hotel volumes.

Continue ReadingBuilding a Hotel Data Lake on AWS That Agrees With the Night Audit

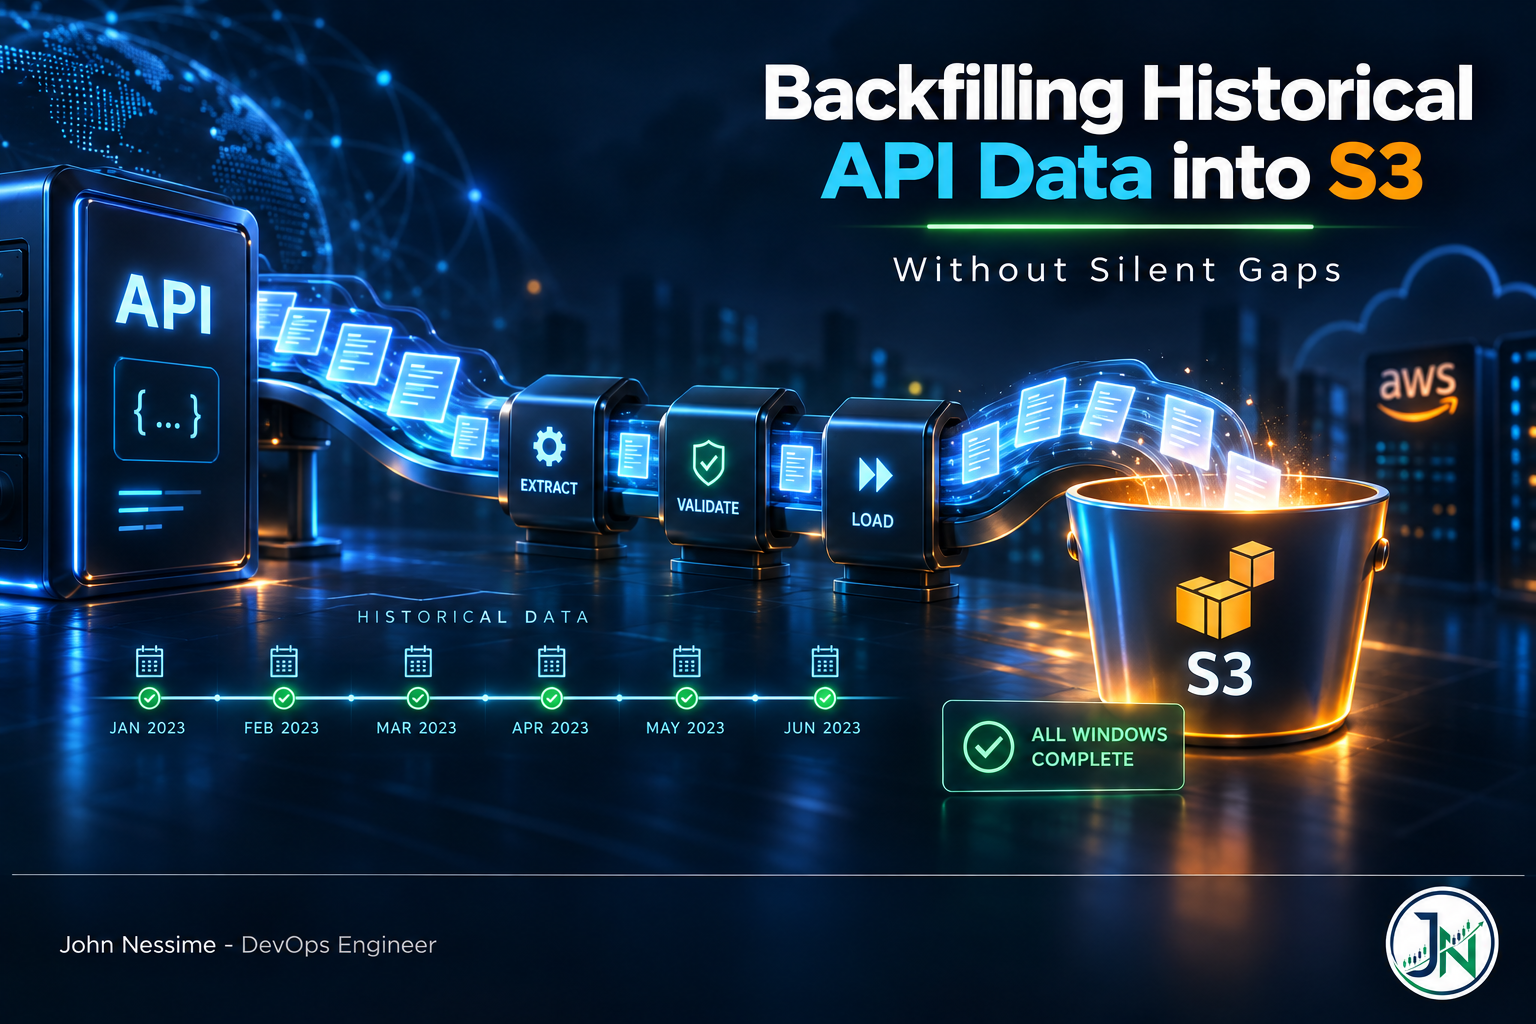
Backfilling Historical API Data into S3 Without Silent Gaps

A backfill that exits zero can still be missing a week of data, and nothing will tell you. This is a practical guide to the failure families behind silent gaps: pagination drift under a mutating source, retries that duplicate pages, prefix layouts designed for writes instead of reads, the seam where backfill meets live ingest, and the storage class rules that make mistakes expensive. Includes deterministic key derivation, S3 conditional writes, Athena partition projection, and a per-window manifest pattern that turns completeness into something you can query.

Continue ReadingBackfilling Historical API Data into S3 Without Silent Gaps

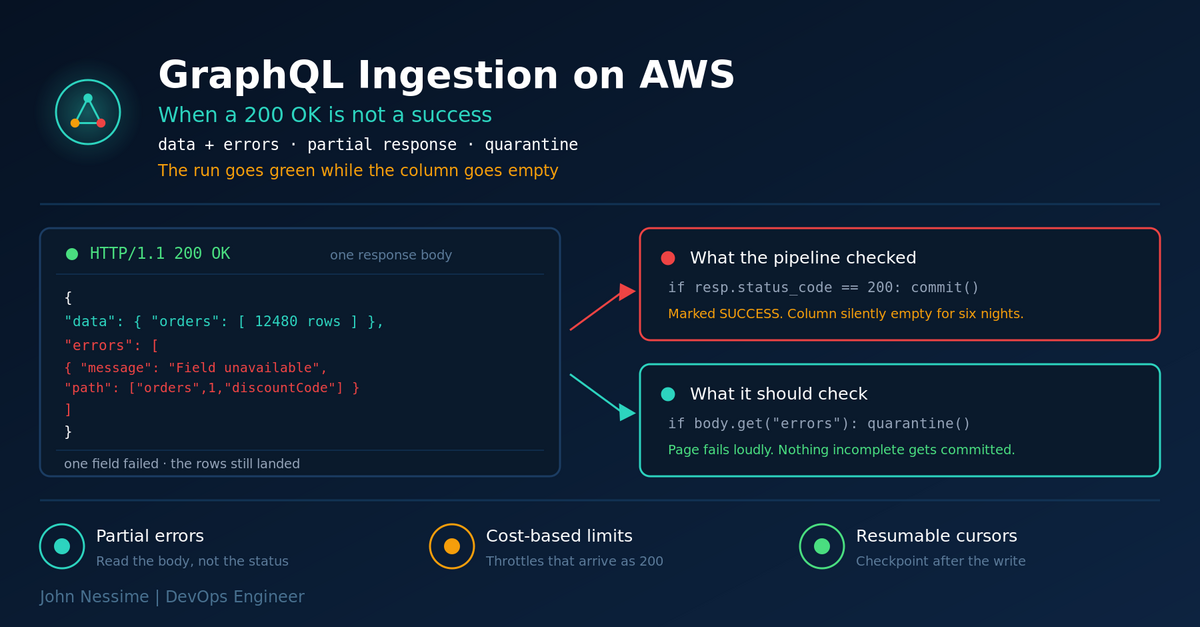
Building a GraphQL Data Ingestion Pipeline on AWS That Doesn’t Lie to You

A GraphQL source can hand you a 200 OK, a populated data block, and a quietly broken column in the same response. Here is how to build a GraphQL data ingestion pipeline on AWS that catches partial errors, respects cost-based rate limits, resumes cleanly from a cursor, and notices when the schema moves under you.

Continue ReadingBuilding a GraphQL Data Ingestion Pipeline on AWS That Doesn’t Lie to You

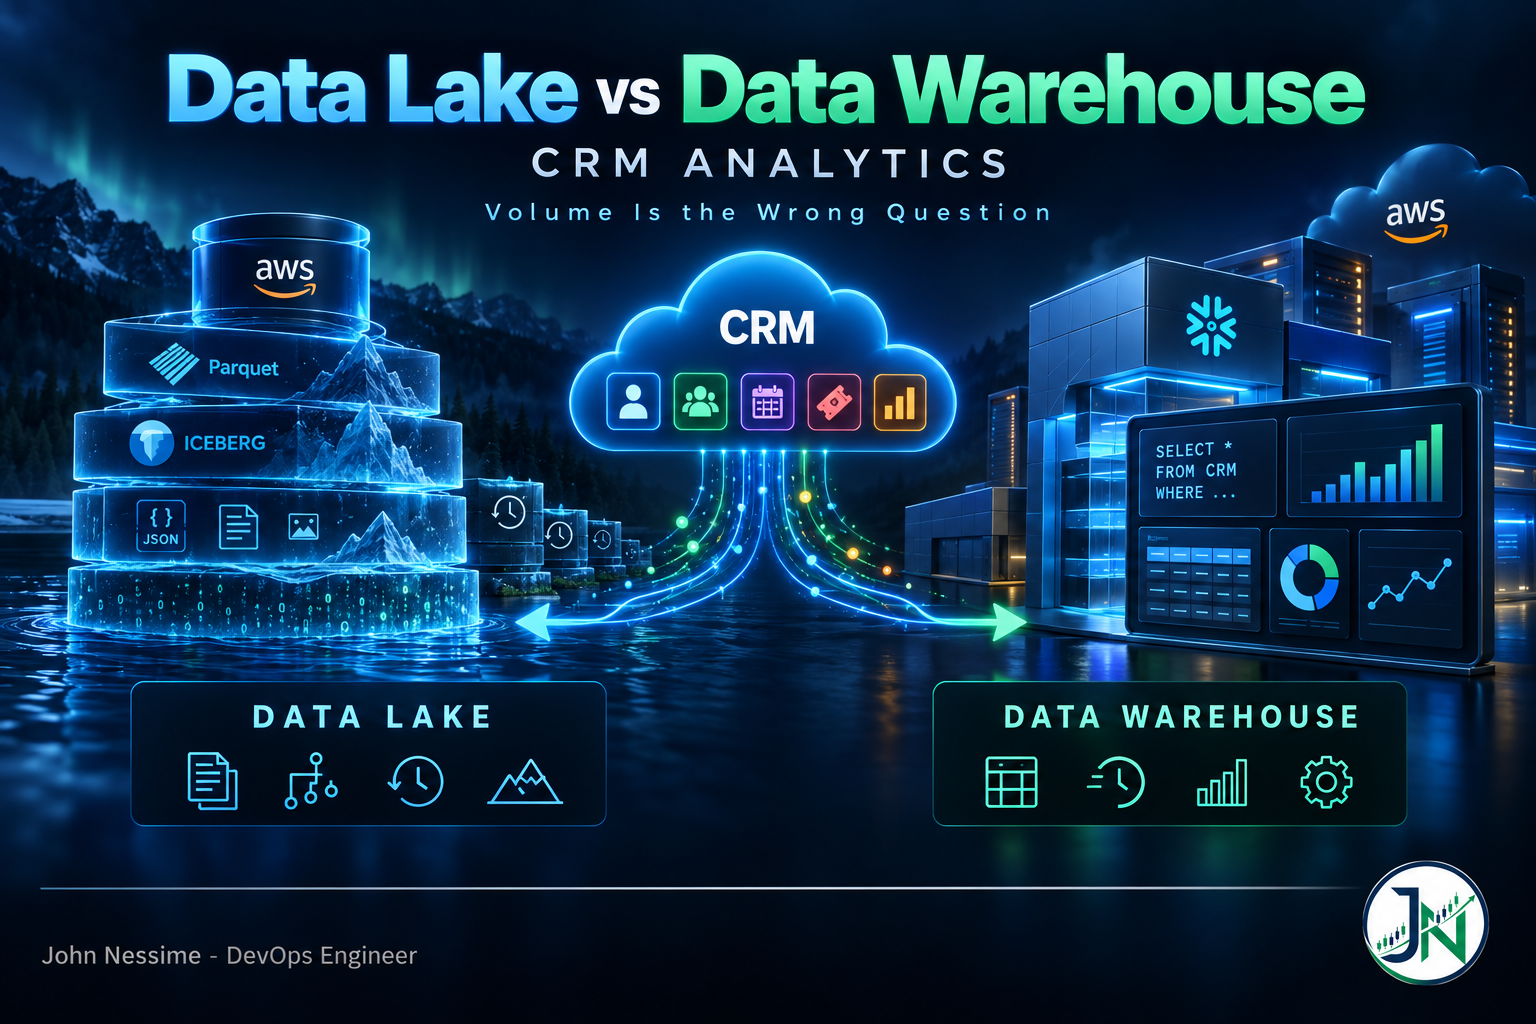
Data Lake vs Data Warehouse for CRM Analytics: Volume Is the Wrong Question

Everyone argues this one on data volume, and volume is the argument that matters least: CRM data is small enough that both architectures handle it comfortably. What actually decides data lake vs data warehouse for CRM analytics is how much point-in-time history you need, how fast the schema churns, what shape your queries are, and who is going to maintain the thing. Includes a decision procedure you can run in an afternoon.

Continue ReadingData Lake vs Data Warehouse for CRM Analytics: Volume Is the Wrong Question

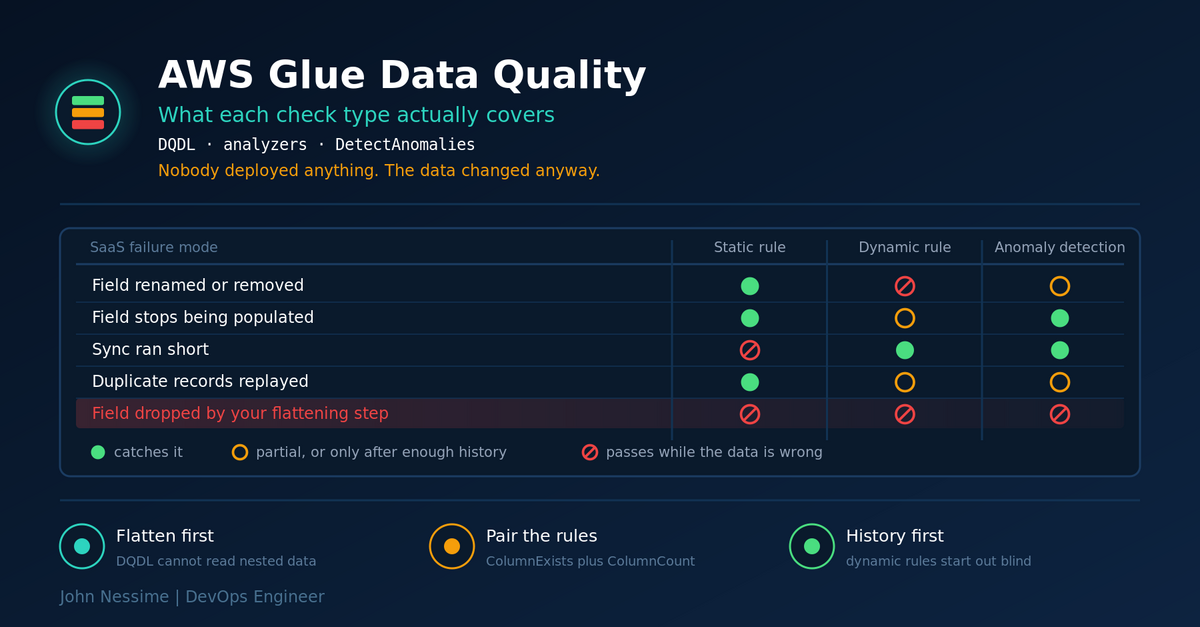
AWS Glue Data Quality for SaaS Data: Catching the Breakage Nobody Deployed

A SaaS admin changes a field and your pipeline stays green while the numbers drift. A practical guide to AWS Glue Data Quality for SaaS sources: where to run the checks, why nested payloads need flattening before DQDL can see them, which rule catches which failure, and the dynamic rules that pass silently because they have no history yet.

Continue ReadingAWS Glue Data Quality for SaaS Data: Catching the Breakage Nobody Deployed