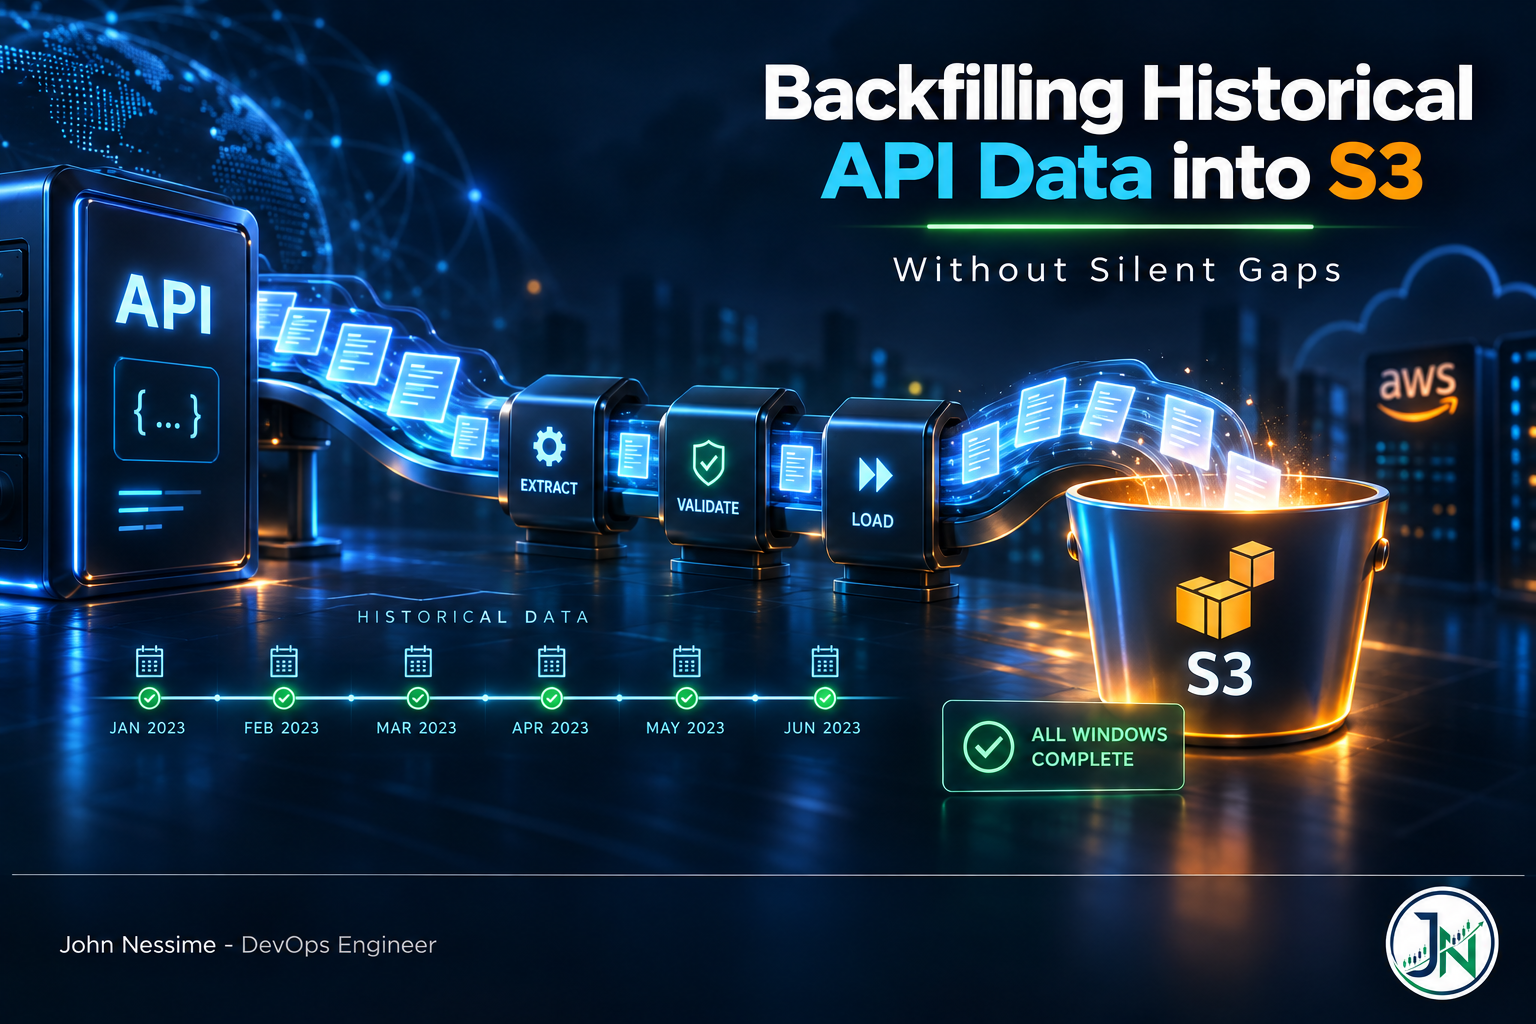
Backfilling Historical API Data into S3 Without Silent Gaps

A backfill that exits zero can still be missing a week of data, and nothing will tell you. This is a practical guide to the failure families behind silent gaps: pagination drift under a mutating source, retries that duplicate pages, prefix layouts designed for writes instead of reads, the seam where backfill meets live ingest, and the storage class rules that make mistakes expensive. Includes deterministic key derivation, S3 conditional writes, Athena partition projection, and a per-window manifest pattern that turns completeness into something you can query.
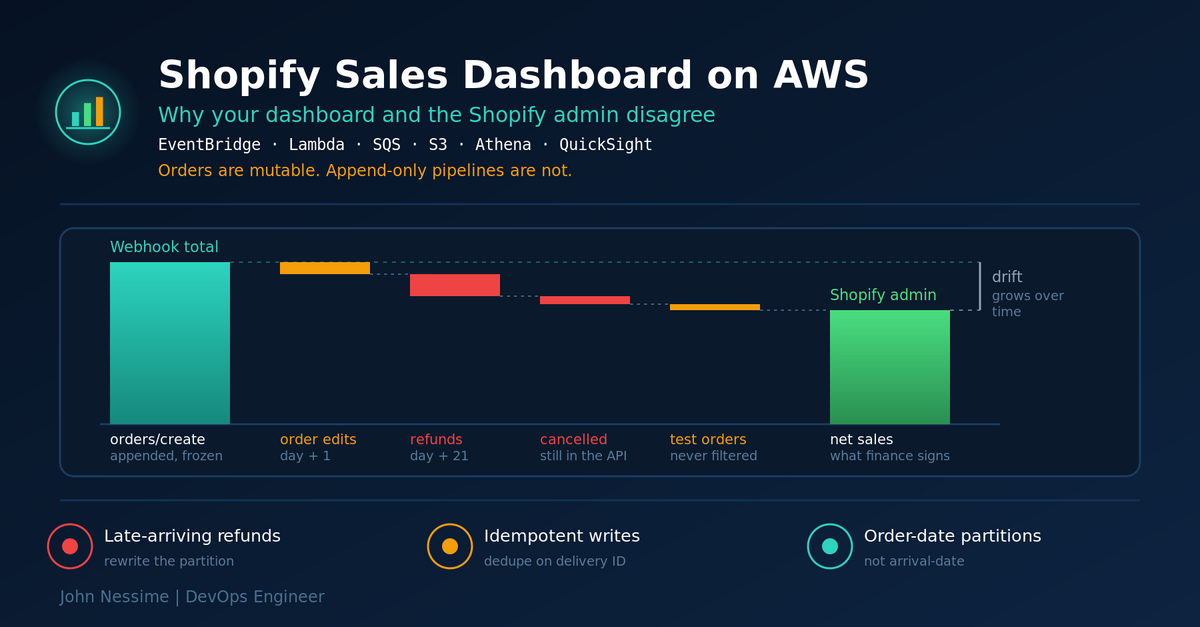
Continue ReadingBackfilling Historical API Data into S3 Without Silent Gaps

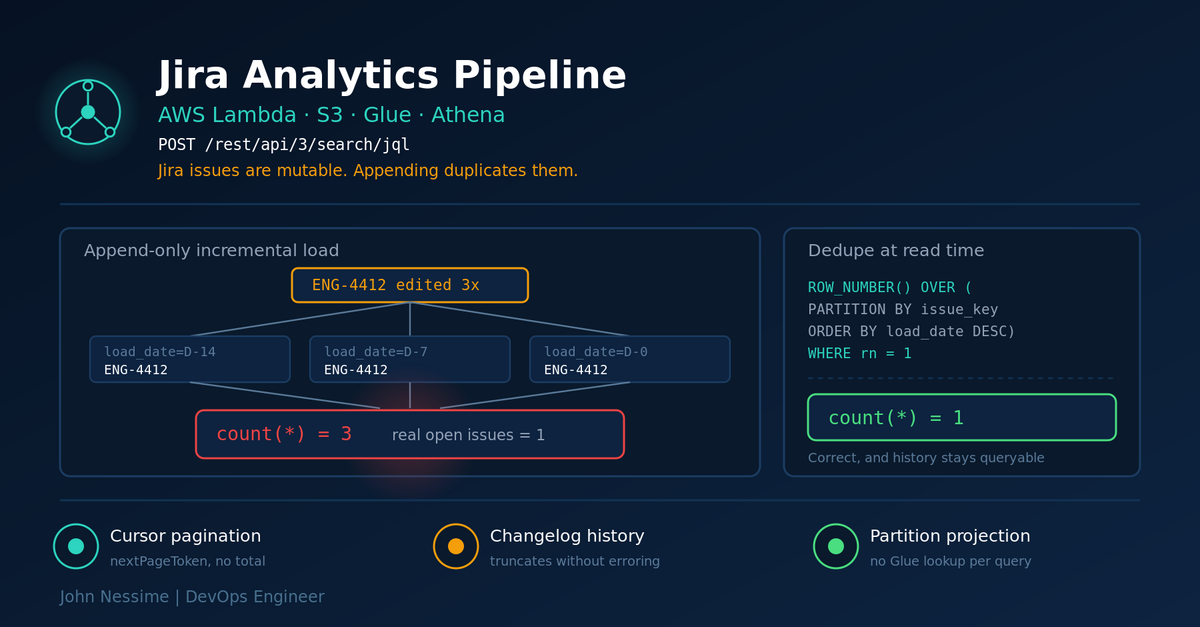
Building a Jira Analytics Pipeline with AWS Lambda and Athena (Without Double-Counting Everything)

Jira's built-in reports stop at the board boundary. This guide walks through a Jira analytics pipeline built on AWS Lambda, S3 and Athena, organised around the four failure families that actually bite: the removed search endpoint, silently truncated changelogs, incremental loads that duplicate rows, and an S3 layout that quietly inflates your query bill.

Continue ReadingBuilding a Jira Analytics Pipeline with AWS Lambda and Athena (Without Double-Counting Everything)