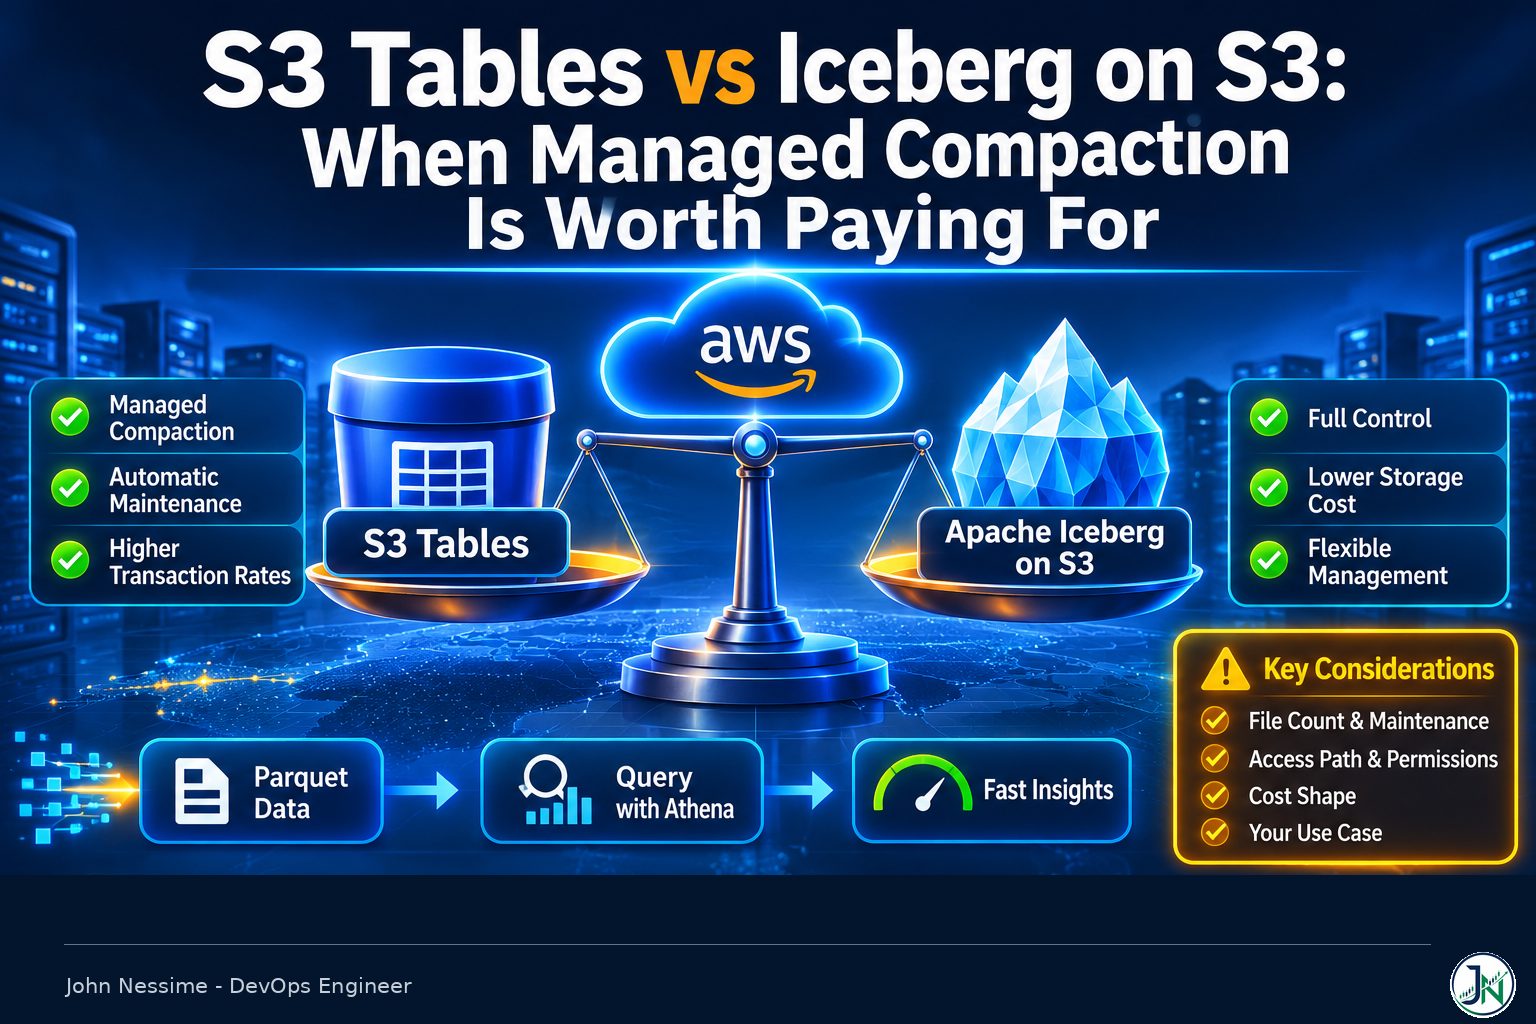
S3 Tables vs Iceberg on S3: When Managed Compaction Is Worth Paying For

Managed Iceberg is not a storage upgrade, it is a decision about who owns compaction, snapshot expiry and orphan cleanup. A practical comparison of S3 Tables against Iceberg in general purpose S3 buckets, covering the maintenance you actually get, the Lake Formation trap in the access path, how the two bills are shaped, and a seven-step decision procedure you can run against a single table.
Continue ReadingS3 Tables vs Iceberg on S3: When Managed Compaction Is Worth Paying For

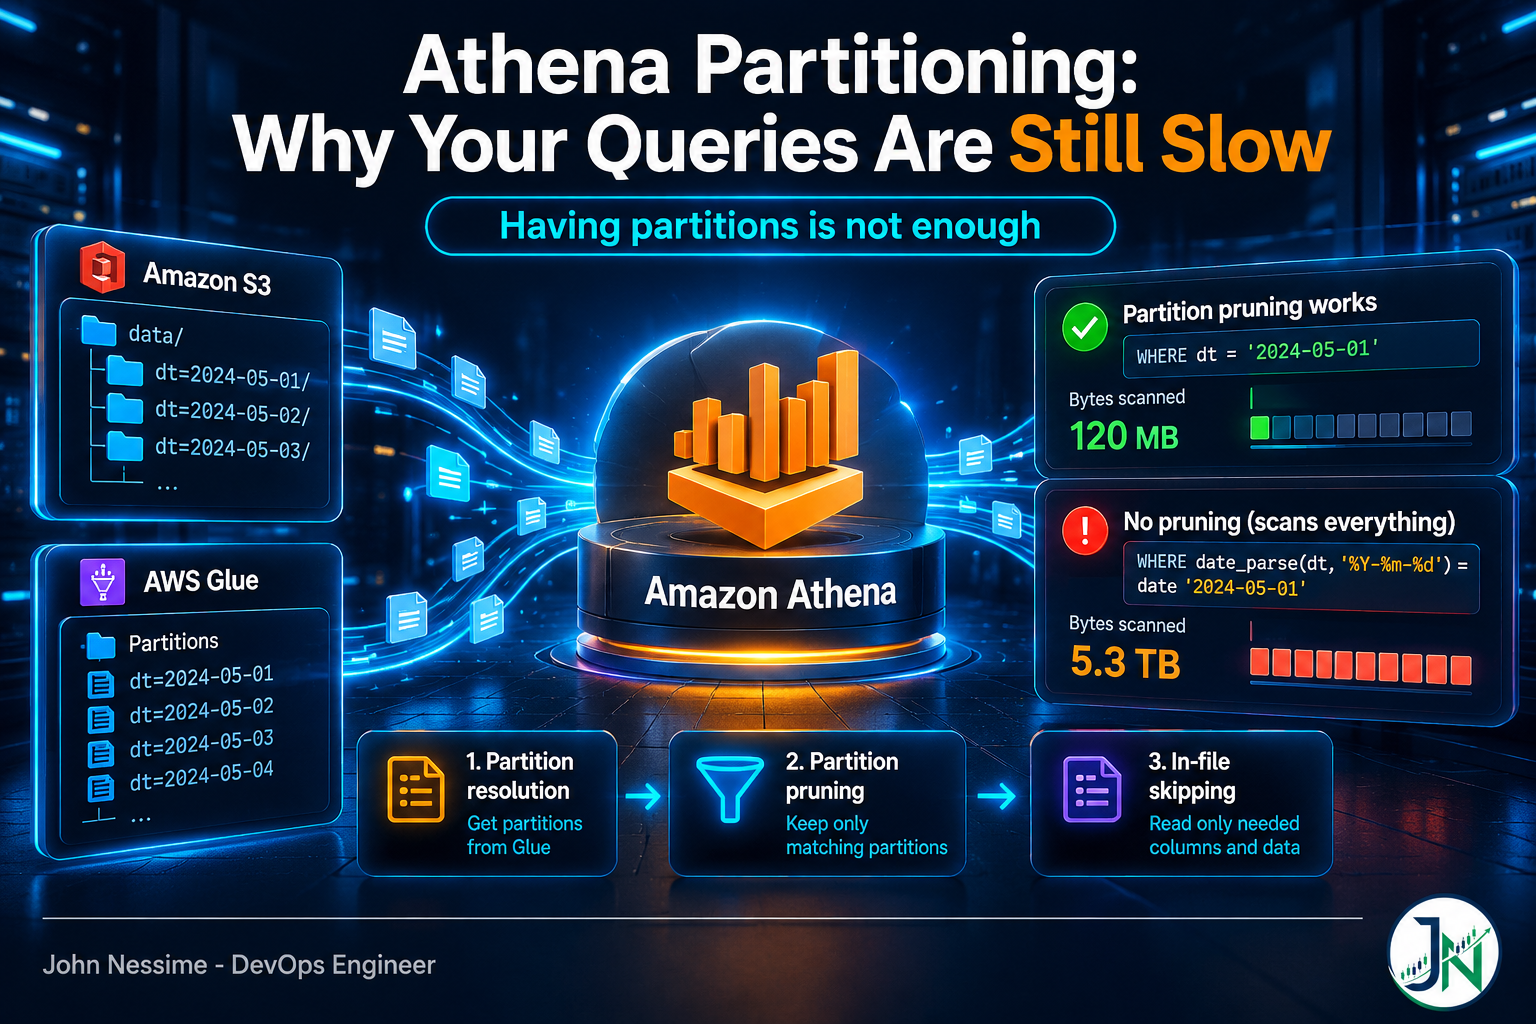
Athena Partitioning: Why Your Queries Are Still Slow

Partitioning an Athena table is not the same as getting the benefit of it. A walkthrough of the three failure families behind slow queries on partitioned external data: predicates that never prune, catalog lookups that dominate planning, and file layouts that undo everything. Includes partition projection trade-offs, Glue partition indexes, compaction patterns, and how to tell which problem you have.

Continue ReadingAthena Partitioning: Why Your Queries Are Still Slow

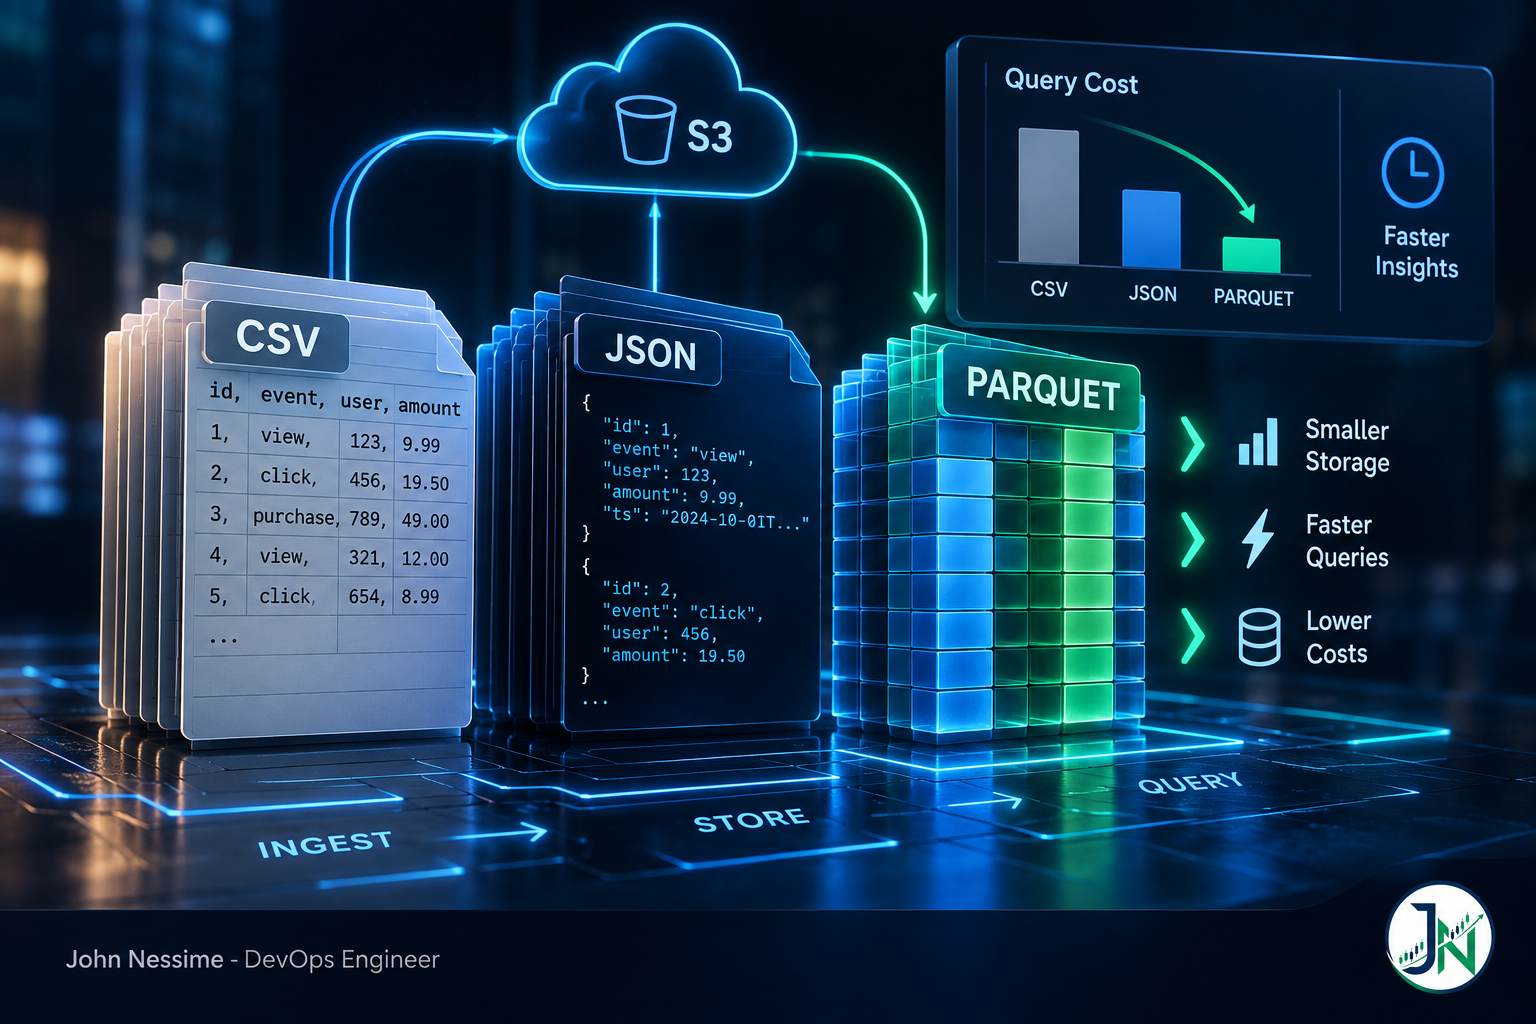
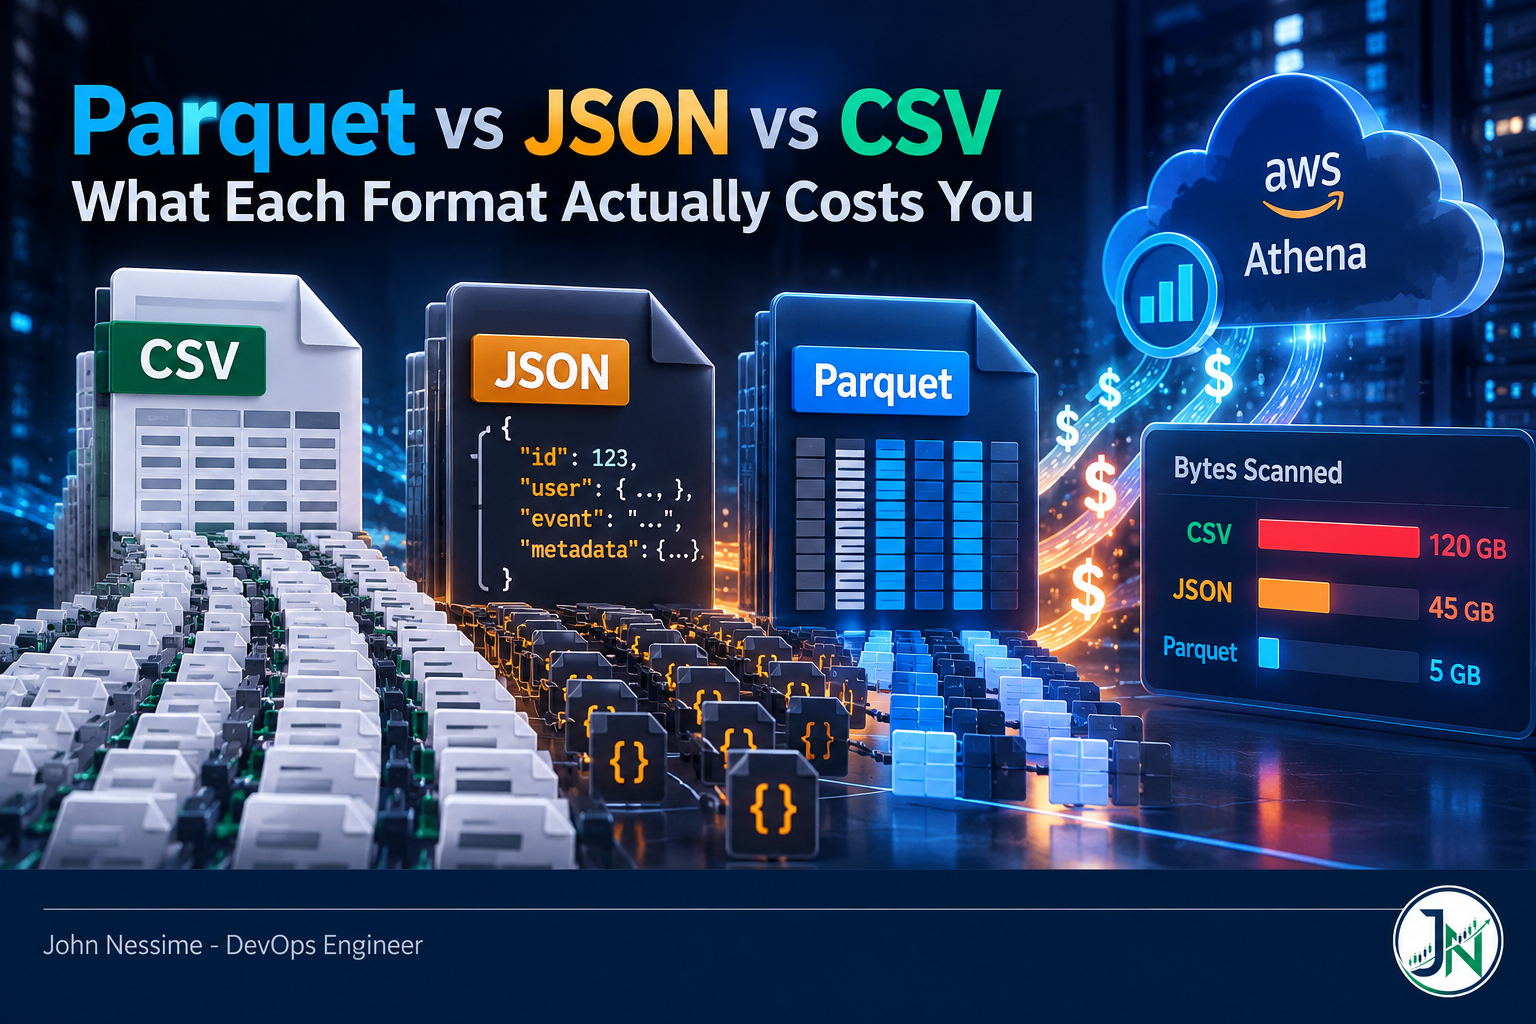
Parquet vs JSON vs CSV: What Each Format Actually Costs You

Format choice shows up as a bill, not a performance complaint. A working breakdown of where the money actually goes across Parquet, JSON and CSV: column pruning, row-group skipping, the gzip splittability trap, and request overhead. Includes a procedure for measuring the difference on your own data, and an honest account of where Parquet costs you.

Continue ReadingParquet vs JSON vs CSV: What Each Format Actually Costs You

S3 Tables Compaction in Production: The Cost of Convenience

Managed Iceberg compaction in S3 Tables removes real operational work, but it will not tell you when it stops. A practical look at the maintenance jobs that fail silently, the retention cascade that keeps superseded data on your bill for two weeks, how compaction charges actually accumulate, and the handful of knobs worth touching.

Continue ReadingS3 Tables Compaction in Production: The Cost of Convenience

Building a Hotel Data Lake on AWS That Agrees With the Night Audit

Hotel source data is mutable in the past, so an append-only pipeline drifts away from the PMS without anyone noticing until month close. A practical guide to room-night grain, bitemporal modeling with Apache Iceberg, PMS ingestion, guest data scope, and file physics at hotel volumes.

Continue ReadingBuilding a Hotel Data Lake on AWS That Agrees With the Night Audit

Amazon Macie PII Detection: The Buckets It Never Opened

A Macie bucket labeled "Not sensitive" often just means Macie never read it. Extensionless objects, unsupported storage classes, unreachable KMS keys and quota truncation all produce silence that looks identical to a clean result. Here's how to measure coverage, fix the four gaps, tune identifiers, and keep the bill honest.

Continue ReadingAmazon Macie PII Detection: The Buckets It Never Opened

Backfilling Historical API Data into S3 Without Silent Gaps

A backfill that exits zero can still be missing a week of data, and nothing will tell you. This is a practical guide to the failure families behind silent gaps: pagination drift under a mutating source, retries that duplicate pages, prefix layouts designed for writes instead of reads, the seam where backfill meets live ingest, and the storage class rules that make mistakes expensive. Includes deterministic key derivation, S3 conditional writes, Athena partition projection, and a per-window manifest pattern that turns completeness into something you can query.

Continue ReadingBackfilling Historical API Data into S3 Without Silent Gaps