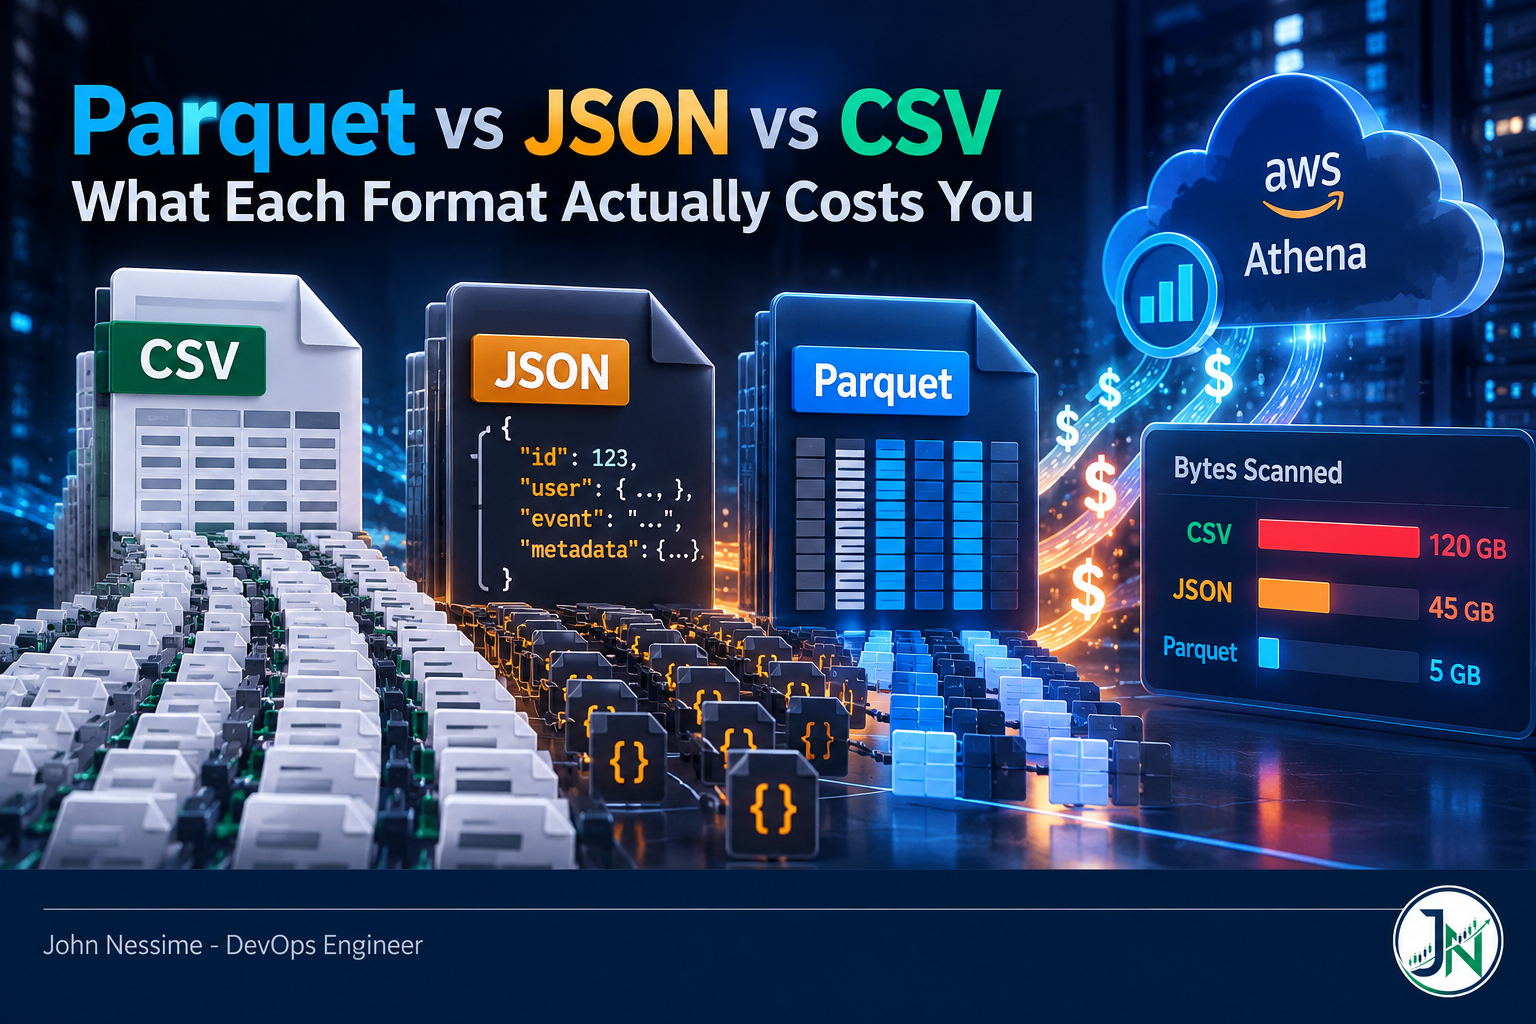
Parquet vs JSON vs CSV: What Each Format Actually Costs You

Format choice shows up as a bill, not a performance complaint. A working breakdown of where the money actually goes across Parquet, JSON and CSV: column pruning, row-group skipping, the gzip splittability trap, and request overhead. Includes a procedure for measuring the difference on your own data, and an honest account of where Parquet costs you.
Continue ReadingParquet vs JSON vs CSV: What Each Format Actually Costs You

S3 Tables Compaction in Production: The Cost of Convenience

Managed Iceberg compaction in S3 Tables removes real operational work, but it will not tell you when it stops. A practical look at the maintenance jobs that fail silently, the retention cascade that keeps superseded data on your bill for two weeks, how compaction charges actually accumulate, and the handful of knobs worth touching.

Continue ReadingS3 Tables Compaction in Production: The Cost of Convenience

Backfilling Historical API Data into S3 Without Silent Gaps

A backfill that exits zero can still be missing a week of data, and nothing will tell you. This is a practical guide to the failure families behind silent gaps: pagination drift under a mutating source, retries that duplicate pages, prefix layouts designed for writes instead of reads, the seam where backfill meets live ingest, and the storage class rules that make mistakes expensive. Includes deterministic key derivation, S3 conditional writes, Athena partition projection, and a per-window manifest pattern that turns completeness into something you can query.

Continue ReadingBackfilling Historical API Data into S3 Without Silent Gaps