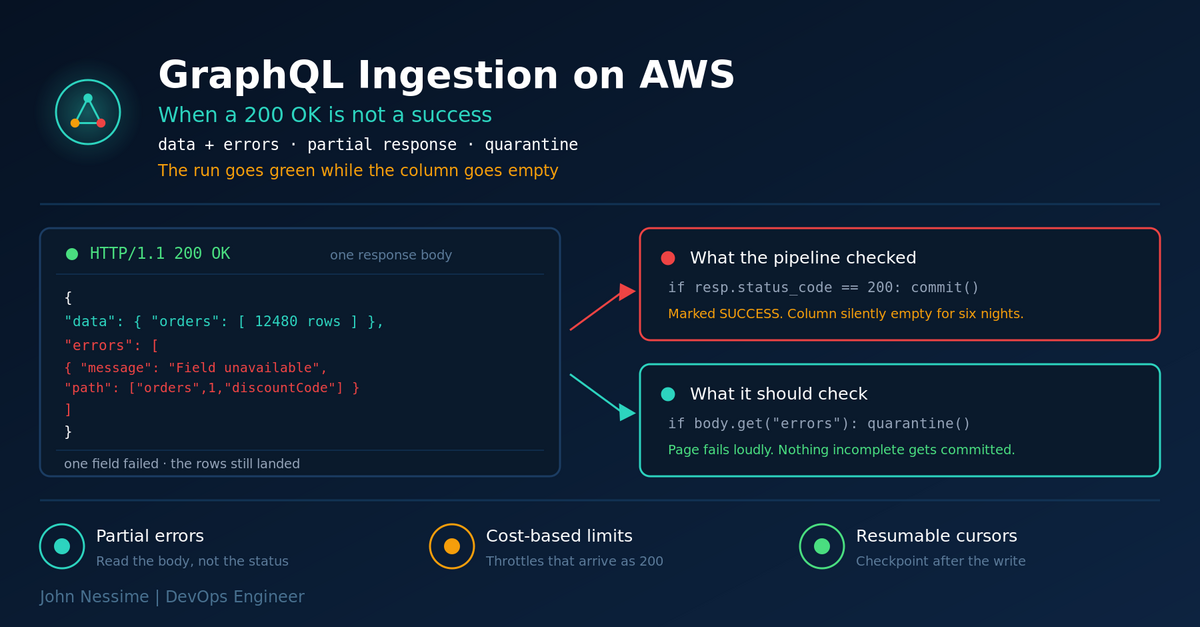
Building a GraphQL Data Ingestion Pipeline on AWS That Doesn’t Lie to You

A GraphQL source can hand you a 200 OK, a populated data block, and a quietly broken column in the same response. Here is how to build a GraphQL data ingestion pipeline on AWS that catches partial errors, respects cost-based rate limits, resumes cleanly from a cursor, and notices when the schema moves under you.
Continue ReadingBuilding a GraphQL Data Ingestion Pipeline on AWS That Doesn’t Lie to You

Optimizing API Calls to Reduce SaaS Costs: Six Levers That Actually Move the Bill

Third-party API spend is the one production signal with no error rate attached to it, which is why it creeps up quietly. This is a working engineer's guide to reducing SaaS API costs by changing the shape of your calls: reading the billing unit before you optimise anything, killing pointless polling with conditional requests and webhooks, collapsing N+1 patterns, caching with stampede protection and per-tenant keys, stopping your own retry amplification, and attributing spend so you can prove the work paid off.

Continue ReadingOptimizing API Calls to Reduce SaaS Costs: Six Levers That Actually Move the Bill

Apache Airflow on AWS: Building SaaS and API Pipelines That Don’t Lie to You

Most API pipeline failures are green DAGs producing incomplete data. A practical guide to running Apache Airflow on AWS for SaaS and API extraction: choosing between MWAA provisioned, MWAA Serverless and self-managed, the pool setting that silently stops throttling when you go deferrable, retry and pagination design, secrets handling, and the four cost lines that actually move.

Continue ReadingApache Airflow on AWS: Building SaaS and API Pipelines That Don’t Lie to You